What is retrieval-augmented generation?
Retrieval-augmented generation (RAG) is a pattern that combines information retrieval with a generative language model. When a user asks a question, the application searches approved knowledge sources, selects relevant passages, and supplies those passages to the model alongside the question. The model then produces an answer using that retrieved context.
The key difference from asking a model to answer from its training alone is that RAG can bring in organization-specific or recently updated information at request time. It can also help an application show where an answer came from. But retrieval does not guarantee that the evidence is complete, current, or interpreted correctly. A RAG system can still return a wrong answer, omit an important exception, or present unsupported claims confidently.
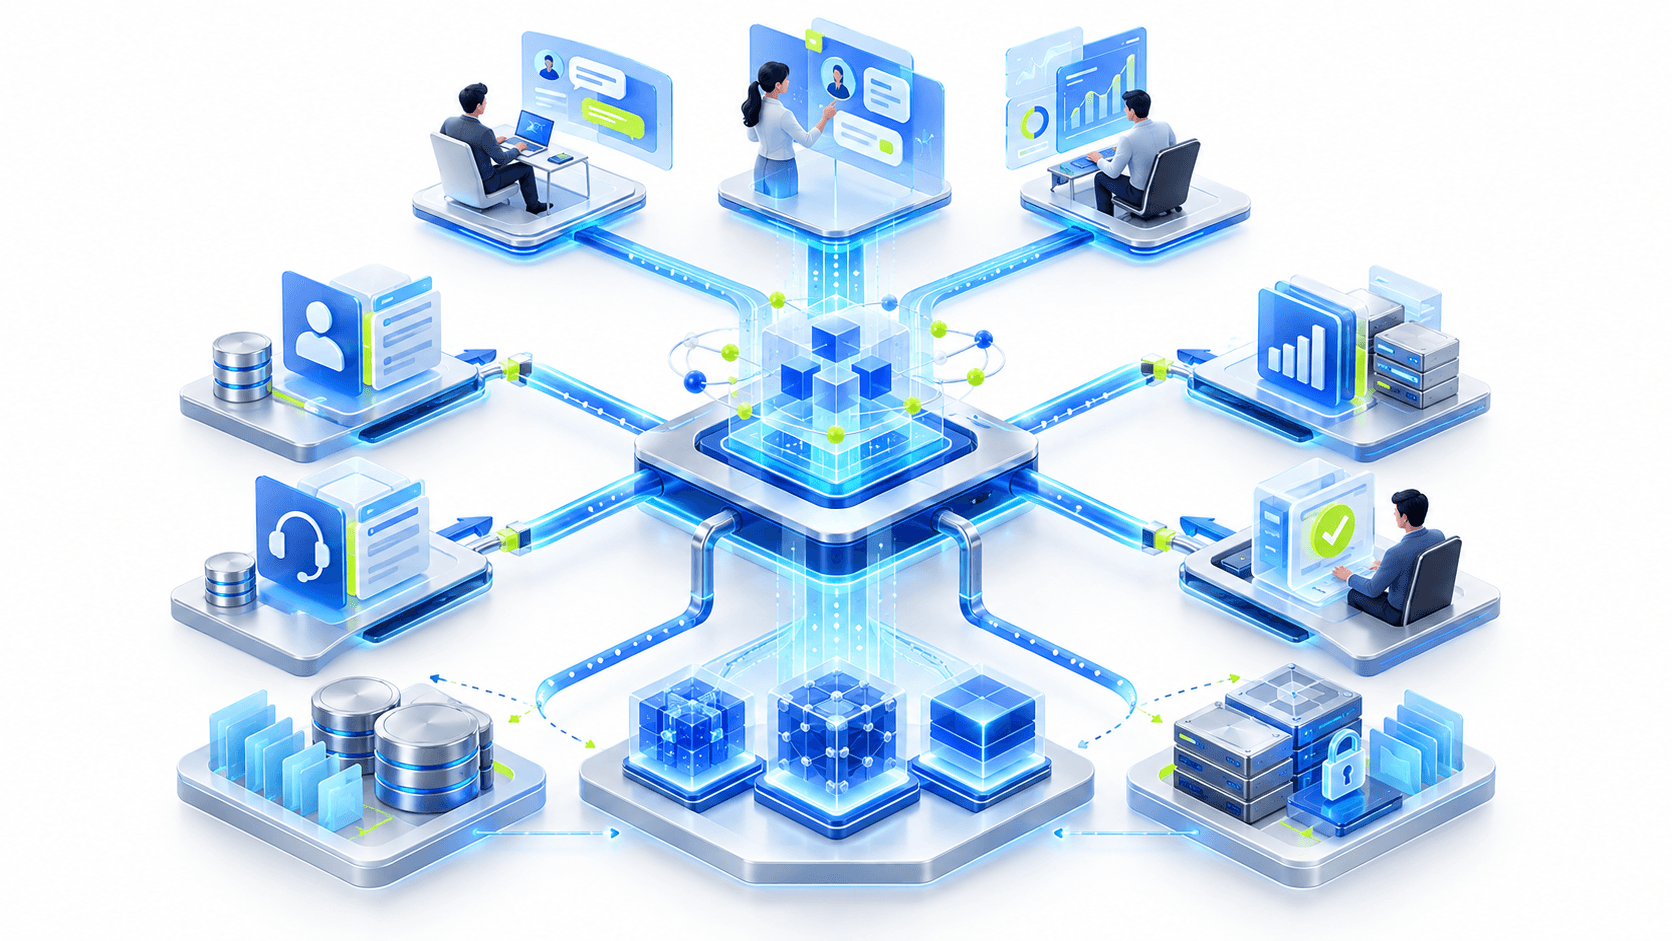
Think of RAG as an application architecture, not a feature you switch on by connecting a vector database. It includes the source systems, ingestion and update processes, search strategy, model, user interface, authorization, evaluation, and operational ownership. A weak link anywhere in that chain can undermine the response, even if the language model itself is capable.
How a RAG system works
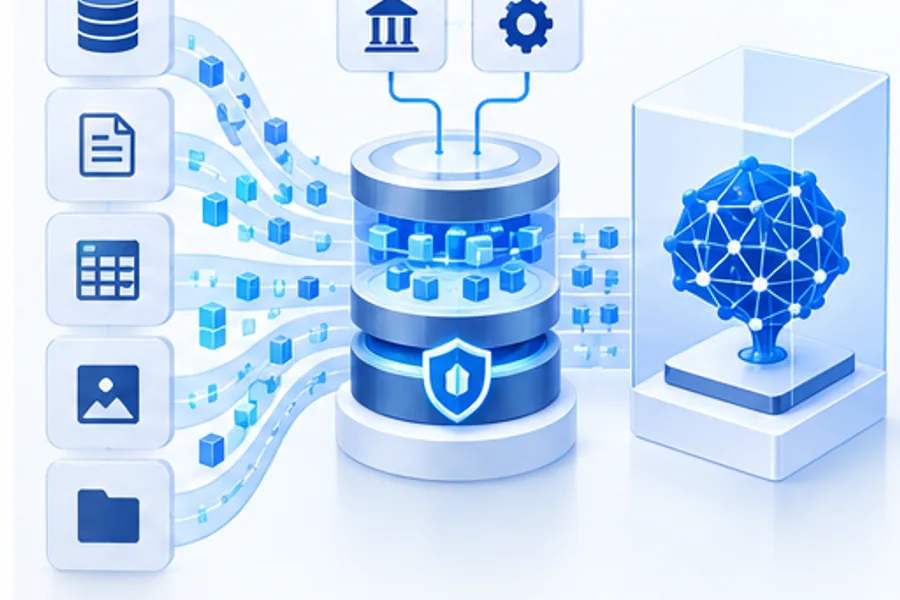
Most systems have two related workflows. During ingestion, the application collects approved documents, extracts their text and structure, divides content into searchable units, attaches metadata, and creates an index. Depending on the design, that index may include vector embeddings, a traditional keyword index, or both. The pipeline should preserve useful context such as document title, section, version, effective date, and access policy.
At query time, the system receives a question, applies the user’s permissions and relevant filters, searches the index, and selects passages for the model. The model receives the question and selected evidence, then generates a response. The application can return citations or links to the original material. These stages are useful diagnostic boundaries: if the answer is poor, first determine whether the right evidence was found before changing the prompt or model.
For example, an employee asking, “Can I expense a hotel for this trip?” may need an answer based on the current travel policy, their region, and the trip date. Retrieval should find the applicable policy and any relevant exception; the response should cite those sections and flag missing details rather than inventing eligibility. If the employee needs a definitive remaining allowance, the assistant should query the expense system rather than infer a number from a document.
Build a dependable knowledge pipeline
Start with sources that have an owner and a clear reason to be included. Identify who maintains each source, how often it changes, which version is authoritative, and whether it is approved for the intended use. A large index of duplicated, obsolete, or contradictory documents can make retrieval less dependable rather than more comprehensive.
Parsing and chunking need to preserve meaning. A fixed-length split may separate a rule from its exception, break a table, or lose the heading that explains a passage. Keep related sections together where practical, retain useful headings and document metadata, and tune chunk boundaries against representative questions. Re-indexing should also handle changed and deleted content so obsolete information does not remain available indefinitely.
Treat ingestion as a repeatable data pipeline. Record which source version produced each indexed passage, make updates idempotent, and surface failed files instead of silently skipping them. Decide how to handle scans, spreadsheets, slide decks, and tables; text extraction can lose layout that carries meaning. For high-value sources, compare extracted content with the original and make it possible to trace a retrieved passage back to its exact document and location.
Retrieve evidence that matches the question
Vector search can find passages that are semantically similar even when they use different words. Keyword search can be more reliable for exact terms such as product codes, policy names, and identifiers. Hybrid retrieval combines these signals; metadata filters can narrow results by source, date, product, or other relevant properties. No single retrieval method is best for every collection, so compare approaches using actual user questions.
A reranker can reorder an initial set of candidates to favor passages that more directly answer the query. It may improve relevance, but it adds latency and cost and should be tested against a simpler baseline. Returning more passages is not always better: excess or repetitive context can obscure the useful evidence. Select enough material to answer the task, preserve its boundaries and provenance, and measure whether the right passages appear near the top.
Retrieval settings are application-specific. A help center with a small number of short articles may work well with straightforward keyword or hybrid search. A large technical library with lengthy manuals may benefit from document-aware chunking, metadata filters, and reranking. Build a small benchmark before tuning: for each question, note which source should answer it, then measure whether that source appears in the retrieved results. This is more useful than choosing a strategy because it is popular or easy to demo.
Generate answers that stay grounded
The generation step should make clear what the model can and cannot conclude from the supplied evidence. Ask it to distinguish source-backed statements from uncertainty, avoid filling gaps with guesses, and say when the retrieved material does not answer the question. If the task requires a calculation, current record, or binding decision, use an appropriate deterministic service or system of record instead of asking the model to infer it from prose.
Citations are useful only when they point to the evidence that supports the associated claim. Test whether citations resolve to the correct source and passage, whether the passage actually supports the statement, and whether important qualifications are preserved. A citation attached to an unsupported answer can create false confidence, so evaluate attribution rather than treating citation presence as a quality score.
Set the response contract around the user’s task. Some experiences need a concise answer and two citations; others need a structured summary, a list of conflicting source versions, or a request for clarification. Define what the system should do when evidence is weak, contradictory, or absent, and ensure the interface makes that state understandable. A graceful “I could not find this in the approved sources” is often more useful than a plausible answer with no basis.
Treat permissions and source content as first-class controls
A RAG application must not retrieve information merely because it exists in the index. Enforce authorization using the requesting user’s identity and the source’s access rules, and apply those controls before restricted passages reach the model. Test access boundaries with users who have different roles, including changes to permissions and removed documents. A prompt instruction to keep information private is not a substitute for application-level access control.
Retrieved documents are data, not trusted instructions. Source text can be misleading, out of date, or contain content that should not direct the model or trigger tools. Keep retrieved context separate from system instructions, limit the model’s authority, and validate any proposed actions in application logic. Define logging, retention, incident handling, and source ownership according to the sensitivity of the information being processed.
Permission design deserves special attention when documents inherit access from folders, groups, or individual records. A shared index may serve users with different entitlements, so access metadata must stay synchronized with the source of truth. If permissions cannot be enforced reliably during retrieval, exclude that source or keep it in a separately authorized index. Do not rely on the model to filter content after restricted text has already entered its context.
Evaluate retrieval and answers separately
Create a test set from realistic questions, expected source passages, correct answers, and cases where the answer is missing or ambiguous. Evaluate retrieval on whether it finds the relevant evidence and ranks it usefully. Then evaluate generation on correctness, groundedness, completeness, citation accuracy, appropriate uncertainty, and policy adherence. Separating these checks shows whether a failure came from indexing, search, context selection, or the model’s use of evidence.
Include edge cases: conflicting documents, outdated policies, tables, acronyms, misspellings, multi-part questions, and questions outside the source collection. Combine automated measurements with human review for cases where meaning or business impact requires judgment. Set acceptance criteria before launch, and rerun the same tests when sources, parsing, embeddings, retrieval settings, prompts, or models change.
For retrieval, useful measures include whether a relevant passage appears in the top results and how highly it is ranked. For generated responses, assess factual correctness, support from retrieved evidence, completeness, citation precision, and whether the system abstains when it should. A single overall score can hide trade-offs: a change might improve answer fluency while reducing groundedness, or improve retrieval while making responses slower. Keep a small, human-reviewed set of examples alongside automated evaluation so teams can investigate regressions.
Operate RAG as a changing production system
Monitor ingestion failures, source freshness, retrieval relevance, answer quality, user feedback, latency, and cost. Track them by workflow and source rather than relying only on an aggregate satisfaction score. When a response fails, preserve enough diagnostic information to trace the source versions and pipeline configuration involved, while handling sensitive content appropriately.
RAG can be a strong fit when an application needs to answer from changing, organization-specific knowledge and users benefit from seeing the source. It may be unnecessary when a normal search page is enough, when a structured API can provide a definitive answer, or when the task is better handled by stable rules. Begin with a narrow use case, compare against a simpler baseline, and expand only when evaluation shows that retrieval improves the outcome.
Assign an owner for each operational layer: source quality, ingestion, retrieval configuration, model behavior, access policy, and user support. Version changes to the corpus and retrieval pipeline as carefully as prompt or model changes. When an incident occurs, teams should be able to answer which sources were available, what the system retrieved, and which configuration generated the response. This traceability turns user reports into actionable fixes rather than prompt tweaks made without evidence.
Choose an architecture that fits the knowledge
A simple RAG design retrieves passages directly from one index and sends them to one model call. This is often the right baseline: it is easier to evaluate, explain, and operate than a chain of agents or specialized retrieval stages. Add complexity only when test results identify a specific gap. For instance, metadata filters may address a need to limit results to a product or region, while a reranker may help when relevant passages are retrieved but consistently appear too low in the results.
Some collections need more than one retrieval path. A structured database may answer questions about current orders or account balances, while documents explain policies and procedures. Route each part of the task to the appropriate source, then combine results with clear provenance. Keep authoritative facts in systems designed to manage them; use document retrieval for the context and explanations those systems do not provide.
Handle ambiguous and multi-step questions carefully
A user may ask a question that hides several needs: “What changed in the new leave policy, and does it affect my team?” The system may need to identify the relevant policy versions, compare the changes, establish which team or region applies, and retrieve access-controlled information. If a necessary detail is missing, asking a clarifying question can be safer and more efficient than retrieving broadly and guessing.
For multi-part questions, break the request into explicit sub-questions, retrieve evidence for each, and keep track of which source supports each part of the response. If the pieces conflict or one is unanswered, communicate that rather than blending them into a smooth but misleading summary. More elaborate query rewriting, decomposition, or iterative retrieval can help in some cases, but each extra model call adds failure modes, latency, and cost. Validate the improvement on representative questions before adopting it.
A practical path from prototype to production
Begin with one user group, one knowledge domain, and a defined job to be done. Gather real questions, identify the authoritative sources, document the current way users find answers, and agree on how success will be measured. Build the smallest end-to-end slice: ingest a limited collection, retrieve evidence, return an answer with usable citations, and capture feedback. Compare it with the existing search or support process before expanding the corpus.
Before a pilot, test quality and access boundaries with representative users and realistic data. Decide what information may be logged, who responds to reported errors, how source updates reach the index, and what happens when retrieval or the model is unavailable. Release to a controlled cohort, review unsuccessful questions and corrections with subject-matter experts, then prioritize fixes at the layer that caused the failure. Expand only after both answer quality and operational responsibilities are understood.