What AI data foundations need to deliver
AI data foundations determine whether systems can use reliable, current, and permissioned business information. Duplicate records, stale documents, missing ownership, and inconsistent definitions can surface as confident but unhelpful answers.
Treat data readiness as part of product design. Decide who owns each source, how freshness is maintained, what access rules apply, and how users can report a problem.
Build the path from source to answer
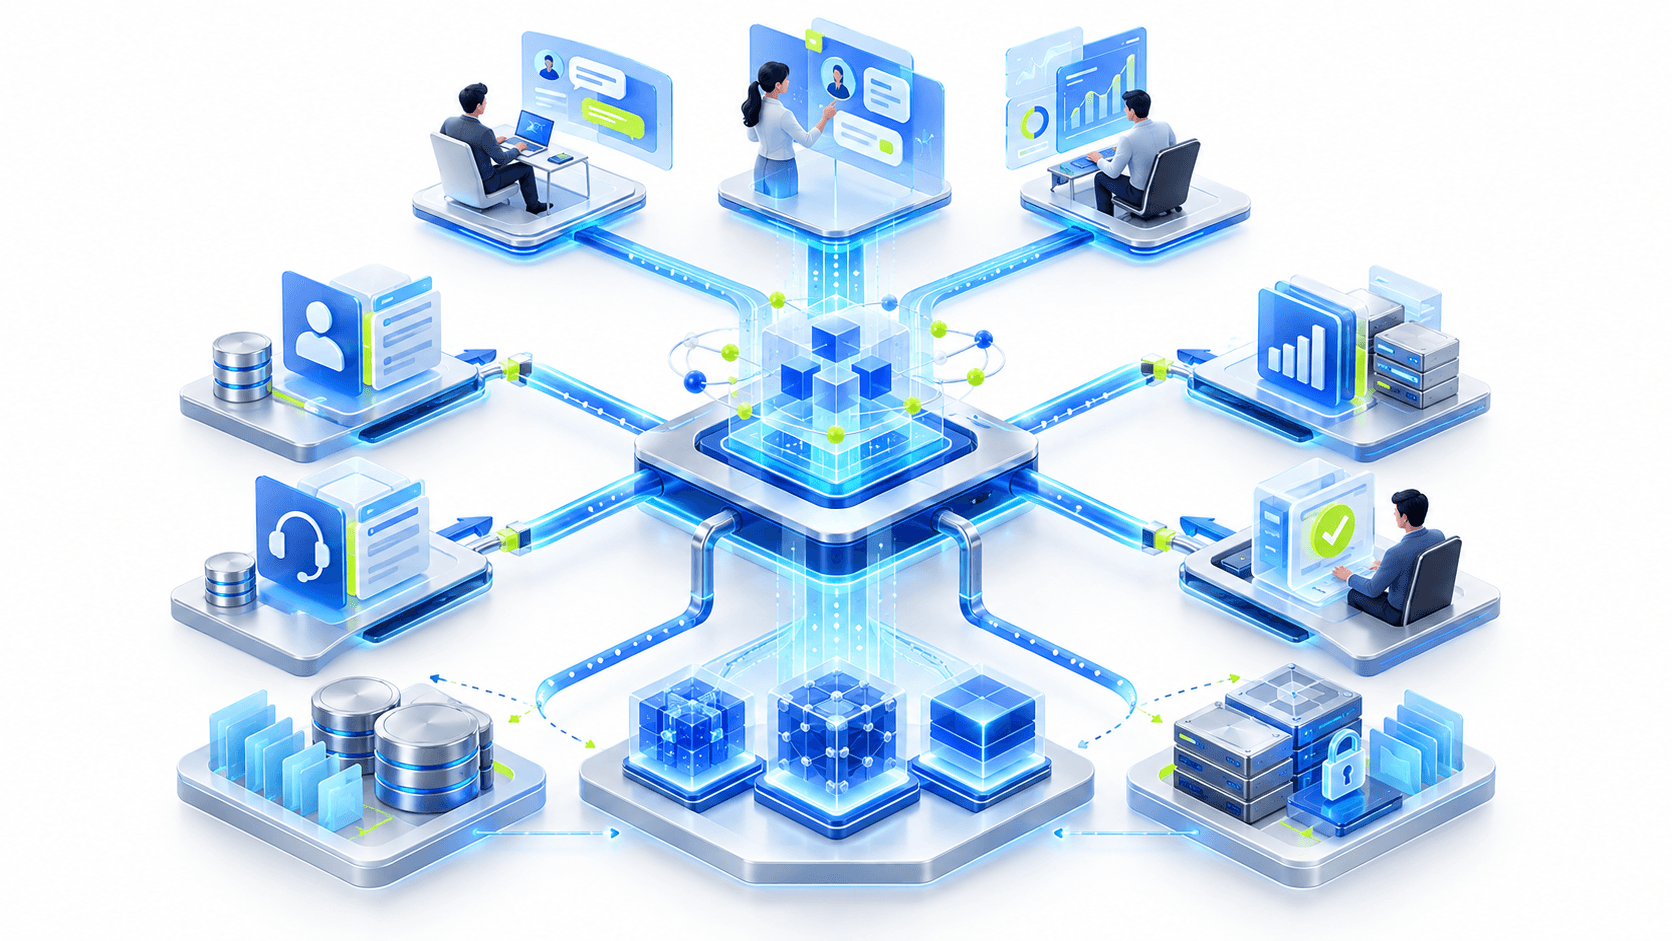
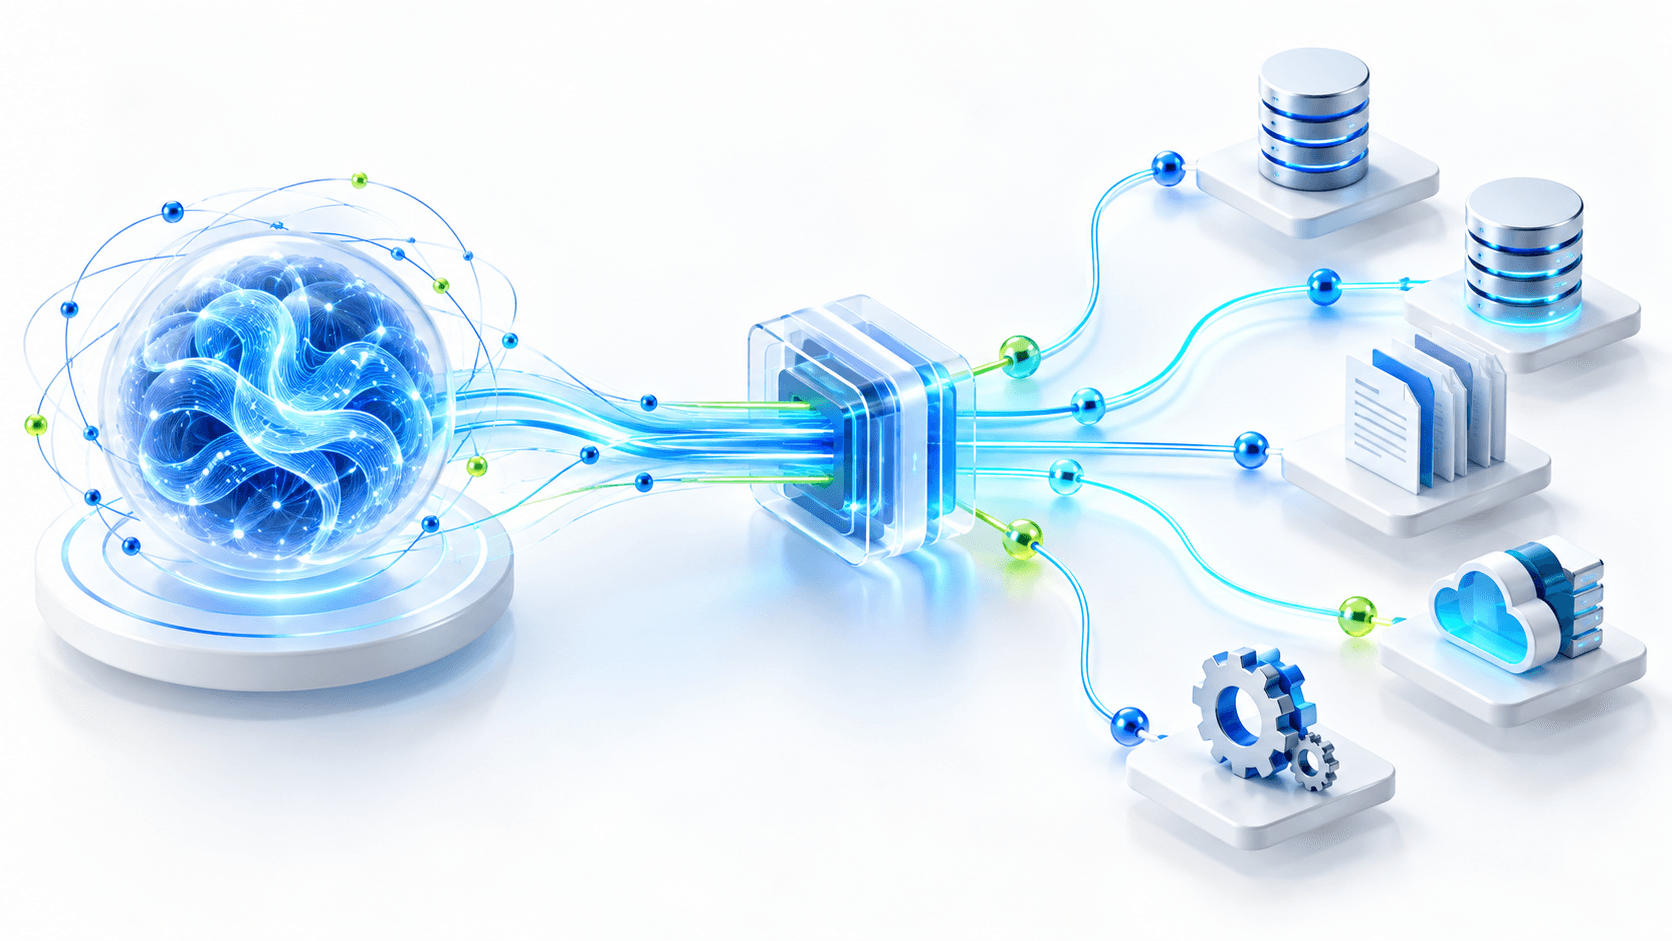
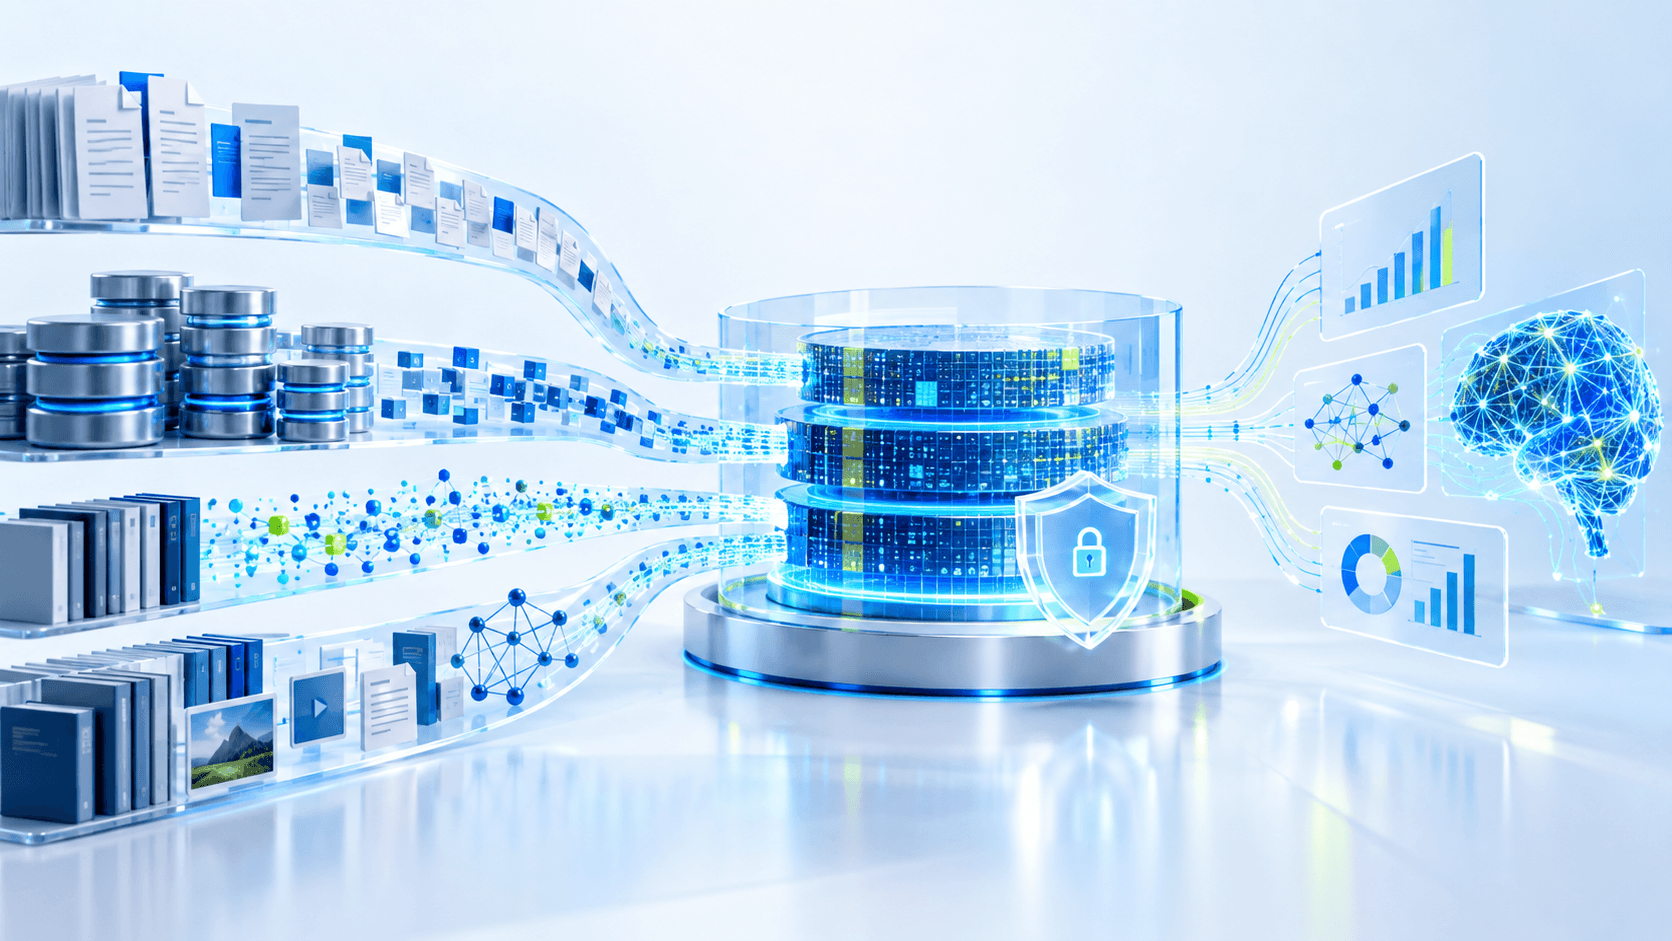
For knowledge assistants, that path includes ingestion, parsing, chunking, metadata, indexing, retrieval, and citations. For analytics, it includes reliable pipelines, shared business definitions, and checks that catch unexpected changes.
The right architecture depends on the use case. A vector database alone does not make a knowledge system trustworthy; retrieval quality, permissions, source context, and evaluation matter just as much.
Make reliability observable
Test representative questions and workflows before launch, then keep evaluating them as the underlying data changes. Monitor freshness, access failures, retrieval quality, and user feedback.
These practices turn data infrastructure into a dependable foundation for AI, and help teams improve the system using evidence rather than guesswork.
Inventory sources before selecting a platform
Begin by listing the sources a proposed AI experience will need: policy documents, product information, customer records, operational events, or curated analytics. For each source, record its owner, system of record, update frequency, access model, sensitivity, and known quality limitations. This inventory often reveals that the real issue is not a missing vector database but conflicting definitions, duplicated records, or no accountable owner for the knowledge.
Prioritize sources according to the questions users need answered. Do not ingest every file just because a platform can. A smaller, authoritative corpus is easier to govern, evaluate, and keep current. Identify which records may be used for retrieval, which require transformation or redaction, and which should remain outside the AI application entirely.
Create contracts for meaning and freshness
Data contracts describe what a source means, which fields are required, how values are defined, and what changes consumers should expect. For customer and operational data, agree on stable identifiers and definitions before building features that join records across systems. For documents, standardize titles, ownership, effective dates, and superseded status so retrieval can distinguish current guidance from historical material.
Freshness is part of correctness. A knowledge assistant that returns an obsolete procedure can be worse than one that says it does not know. Set service expectations for ingestion delay, establish a process for urgent updates, and show the source and its date in the user experience. For time-sensitive facts, consider retrieving from the authoritative API at answer time instead of relying solely on a periodically refreshed index.
Choose the right retrieval and analytics pattern
Different questions need different data paths. Full-text search works well for exact terms; semantic retrieval helps with varied wording; hybrid search can combine both. Structured questions such as “how many open cases exceed the service target?” should usually run through governed analytics or a validated query service, not ask a language model to estimate from a pile of documents.
For retrieval-augmented generation, test parsing, chunk size, metadata filters, ranking, and citation behavior as a chain. A document can be present in the index and still be effectively invisible if tables are parsed badly or the chunk separates a rule from its exception. Evaluate whether the right passage is retrieved before judging the model’s answer. This helps teams fix the actual layer causing a failure.
Protect privacy, permissions, and provenance
Apply access controls before retrieval, not only after a response is generated. The user should not receive a summary of a document they were not authorized to read. Where access varies by person, group, region, or case, propagate those claims into retrieval filters and verify them in tests. Minimize personal data, define retention periods, and make the data flow understandable to security and privacy reviewers.
Keep provenance from ingestion through answer. Store document identifiers, versions, timestamps, transformations, and source links. When information is transformed or summarized, retain enough lineage to investigate discrepancies. Provenance supports debugging and review; it also makes users more likely to trust a system when they can inspect the source behind an answer.
Operate the foundation as a product
Assign owners for pipelines, schemas, quality checks, access policy, and incident response. Monitor failed ingestion, unexpected volume changes, stale sources, query latency, retrieval coverage, and cost. Make data defects easy to report and route reports to the team that can correct the source rather than only patching the prompt.
A useful release gate includes representative questions, expected source passages, permission tests, and a review of low-confidence or no-answer cases. Re-run this suite after source changes, parser upgrades, embedding changes, or model updates. The result is not a one-time “AI-ready” badge; it is a maintained service whose reliability is visible to the teams depending on it.
Choose a roadmap that earns trust step by step
Decision-makers do not need to rebuild every data platform before testing an AI use case. Choose one workflow, identify the minimum authoritative sources, and prove the complete path from access check to answer and source citation. This vertical slice will expose practical gaps in permissions, document parsing, business definitions, and user expectations. Use those findings to prioritize shared improvements rather than launching a broad platform program with no validated consumer.
As the portfolio grows, reuse the controls and observability that have proved useful: catalogued sources, identity-aware retrieval, quality checks, cost monitoring, and evaluation sets. Keep a distinction between experimental and production data paths, and document where sensitive information is processed. A phased roadmap allows the organization to learn from a real user outcome while steadily improving its data estate.
Make the operating contract visible to application teams. Document expected availability, freshness, access behavior, known limitations, and a contact for data incidents. When a source is delayed or withdrawn, dependent AI experiences should degrade clearly: show that information is unavailable, return a safe no-answer, or route the user to an alternative channel instead of silently presenting stale results.