Moving an AI pilot to production takes more than accuracy
Moving an AI pilot to production requires more than strong benchmark results. If employees must switch tools, verify every answer manually, or guess when it is safe to rely on the output, adoption will stall.
Observe the real workflow and design around the moments where AI can reduce friction. Make sources, uncertainty, and next actions visible, and preserve a straightforward way to correct or escalate.
Plan the operating model early
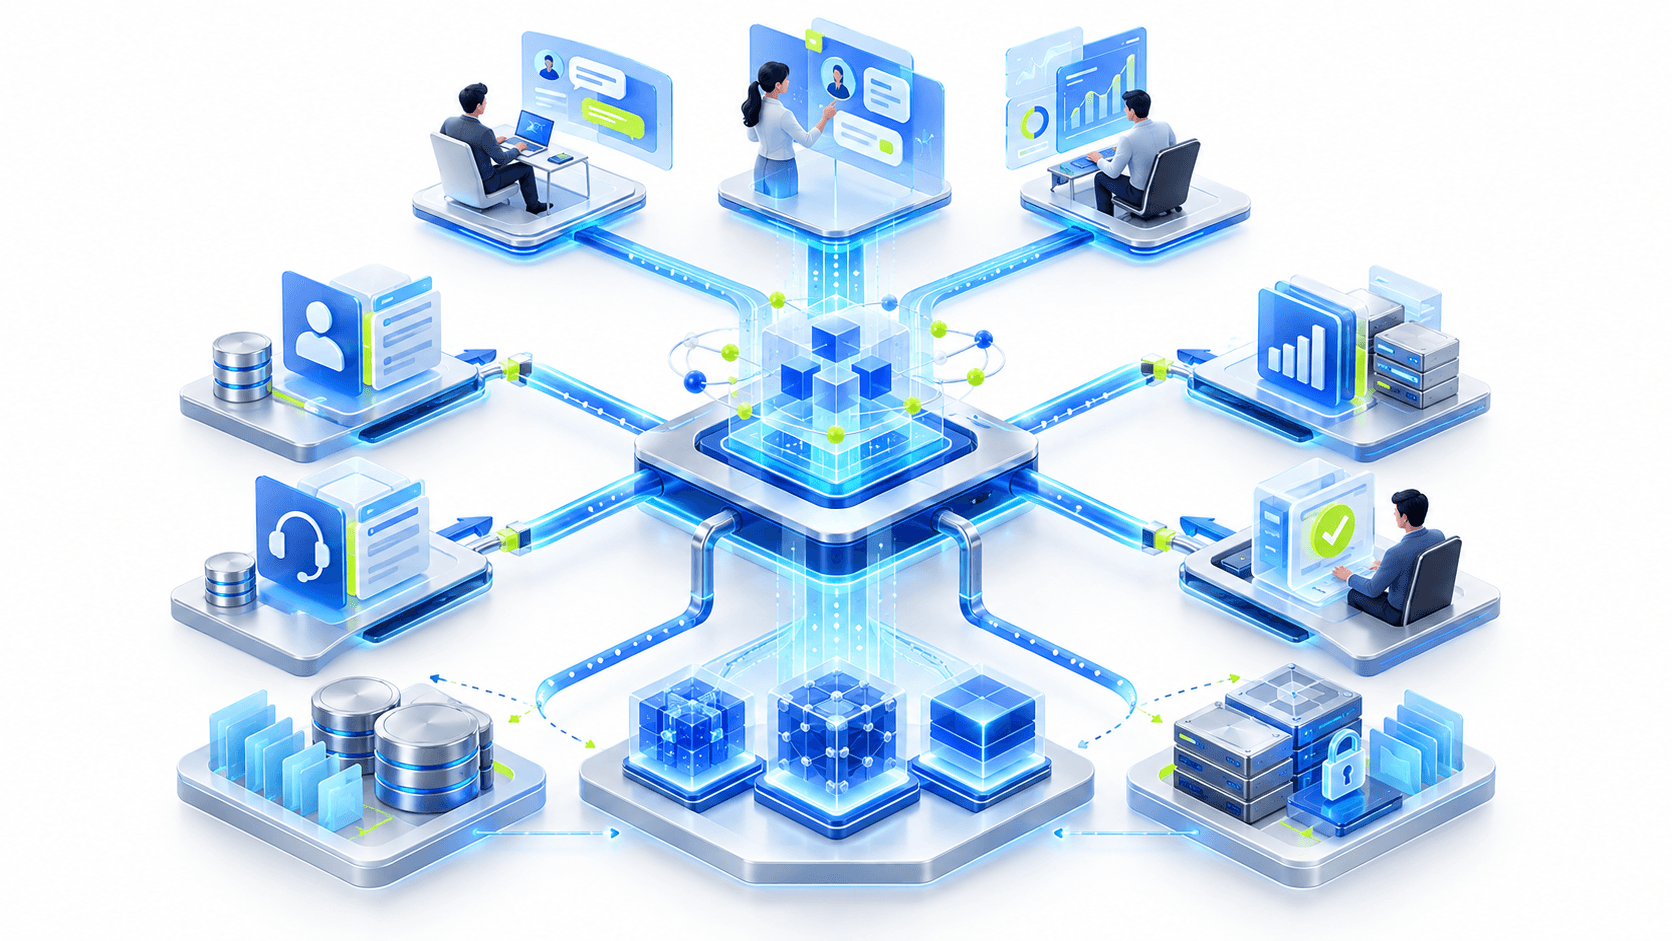
Production systems need named owners for the product, data, security, and operational response. Teams should know how quality is reviewed, how incidents are handled, and how prompts, models, and integrations are changed.
Bring these questions into the pilot. Retrofitting governance and support after a system has spread across teams is harder than designing practical controls from the start.
Scale with evidence
Choose a small set of measures tied to the business goal: cycle time, service quality, resolution rate, employee effort, or another outcome the team can verify. Pair those measures with system quality, safety, and cost signals.
Use the results to decide what to improve and where to expand. A deliberate path from prototype to production gives teams a clearer investment case and a system people can trust.
Explore: AI strategy and consulting services
Write an outcome brief before building
A production-minded pilot starts with a short outcome brief. Name the user, the task, the current workaround, the systems involved, the expected benefit, and the cost of a wrong result. Define what is explicitly out of scope. This prevents a demonstration from quietly becoming a high-impact decision service without the controls, evidence, or ownership that such a change would require.
Baseline the process using data the business already trusts. Depending on the use case, track time to resolution, first-contact resolution, review effort, defect escape rate, completion rate, or customer effort. Write down how the measure is calculated and who validates it. If the team cannot agree on a baseline, use discovery to repair the measurement before claiming that AI has improved the process.
Test the experience with real users and real cases
Select a representative set of cases, including common requests, unusual phrasing, missing information, edge conditions, and examples where the system should refuse or escalate. Include the people who do the job in test design; they know which details look minor to an engineer but change the correct decision. Keep a held-out set so repeated tuning does not make the evaluation look better than actual performance.
Test the user journey, not just output quality in a notebook. Can users see where an answer came from? Can they edit a draft, correct a mistaken assumption, and reach a person without starting over? Observe whether recommendations fit existing systems and permissions. A useful pilot removes work from the process rather than shifting verification effort onto employees or customers.
Build quality and security into the release path
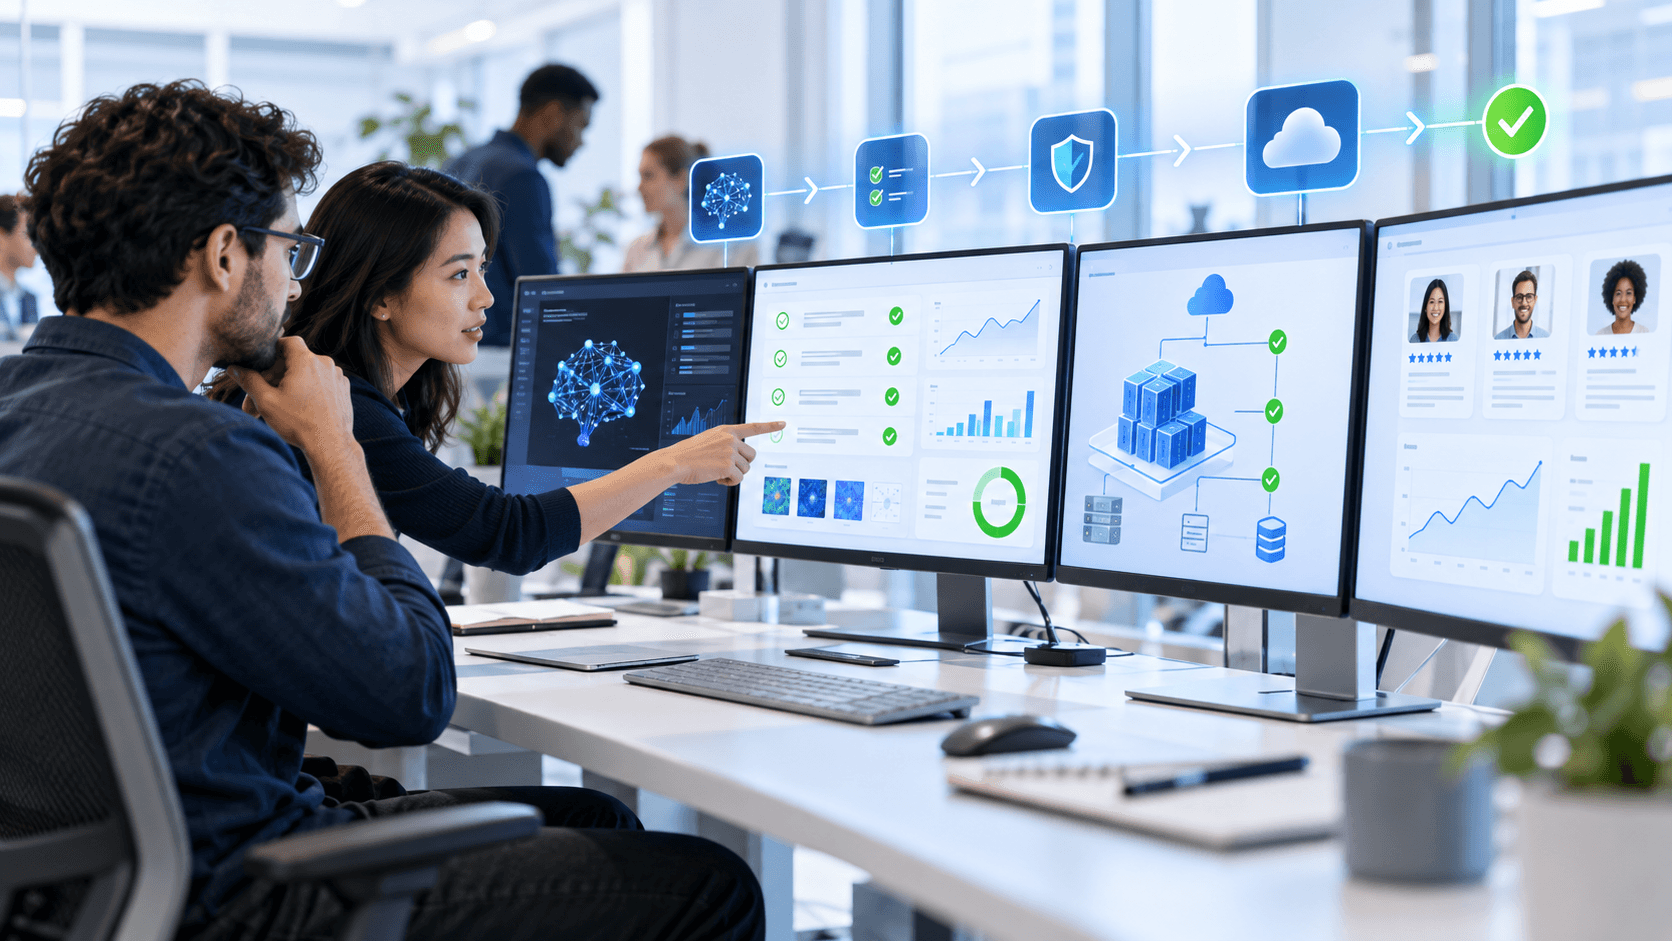
Treat prompts, retrieval configuration, tools, models, and application code as versioned components. Use repeatable evaluations in CI where practical and add regression cases whenever a production issue is found. For software engineering use cases, retain peer review, static analysis, dependency checks, and security scanning. AI-generated code still has to satisfy the same reliability and ownership standards as other code.
Threat-model the complete path, including indirect prompt injection in retrieved documents, data leakage, insecure output handling, over-permissioned tools, and abuse of costly endpoints. Apply least privilege, input validation, output checks, secrets management, rate limits, and logging with privacy controls. Run red-team exercises against the interactions the system is allowed to perform, not just against its public chat interface.
Explore: AI engagement and delivery models
Prepare the people and service operations
Give users role-specific guidance: what the tool is for, when to verify, what information must not be entered, how to report an issue, and how to override or escalate. Managers need a clear explanation of how the system affects accountability and workload. Invite frontline users to review failures and improvements so training reflects actual experience rather than generic prompt tips.
Assign a product owner, technical owner, data owner, and operational responder. Define service hours, incident severity, model or prompt change approval, vendor escalation, and communication with affected users. A service desk should be able to identify the version involved, follow a trace, and route the issue. This is the practical operating model behind AI Service Management: lifecycle ownership rather than “deploy and forget.”
Use staged rollout to earn the right to scale
Move from offline tests to shadow mode, then to a limited cohort with explicit monitoring. Shadow mode lets the team compare AI suggestions with existing decisions without letting the model act. In the next phase, keep human approval for meaningful actions and record overrides. Broaden access only after the system meets quality, safety, cost, and support thresholds over a representative period.
Set rollback triggers before release: rising error or escalation rates, a data source falling behind, unexpected spend, or a serious safety incident. Review trends with process owners on a regular cadence and decide whether to improve, pause, or retire the feature. Scaling is not the goal by itself; the goal is repeatable business value at an acceptable level of risk and ongoing operating effort.
Calculate value across the whole service
A credible return-on-investment view includes more than model inference. Account for integration work, data curation, evaluation, platform operations, human review, training, and the cost of handling failures. Estimate how much of the time saved can be converted into faster service, more resolved cases, or capacity for higher-value work. Separate observed results from projected benefits and state the assumptions behind both.
Review distribution as well as averages. A system may be highly effective for common requests while adding effort for a specific customer segment or complex case type. Track who benefits, where additional review is needed, and whether quality remains consistent across relevant groups. These signals help leaders decide whether to expand the use case, improve a weak part of the workflow, or stop investing.