Where onboarding time is really spent
Business and consumer onboarding often requires collecting identity records, tax documents, statements, ownership information, and application details. Staff may spend time identifying document types, finding fields across many pages, rekeying data, reconciling inconsistent names or addresses, and requesting missing pages. OCR and document intelligence can reduce manual handling, but they do not replace the institution’s customer-identification and due-diligence obligations.
A “days to minutes” headline is best understood as an automation objective for the document-processing portion of complete, eligible cases. External verification, risk review, missing evidence, sanctions screening, beneficial-ownership checks, and customer follow-up can still take longer. Measure elapsed time by stage and publish the scope of any performance claim.
A controlled OCR-to-review workflow
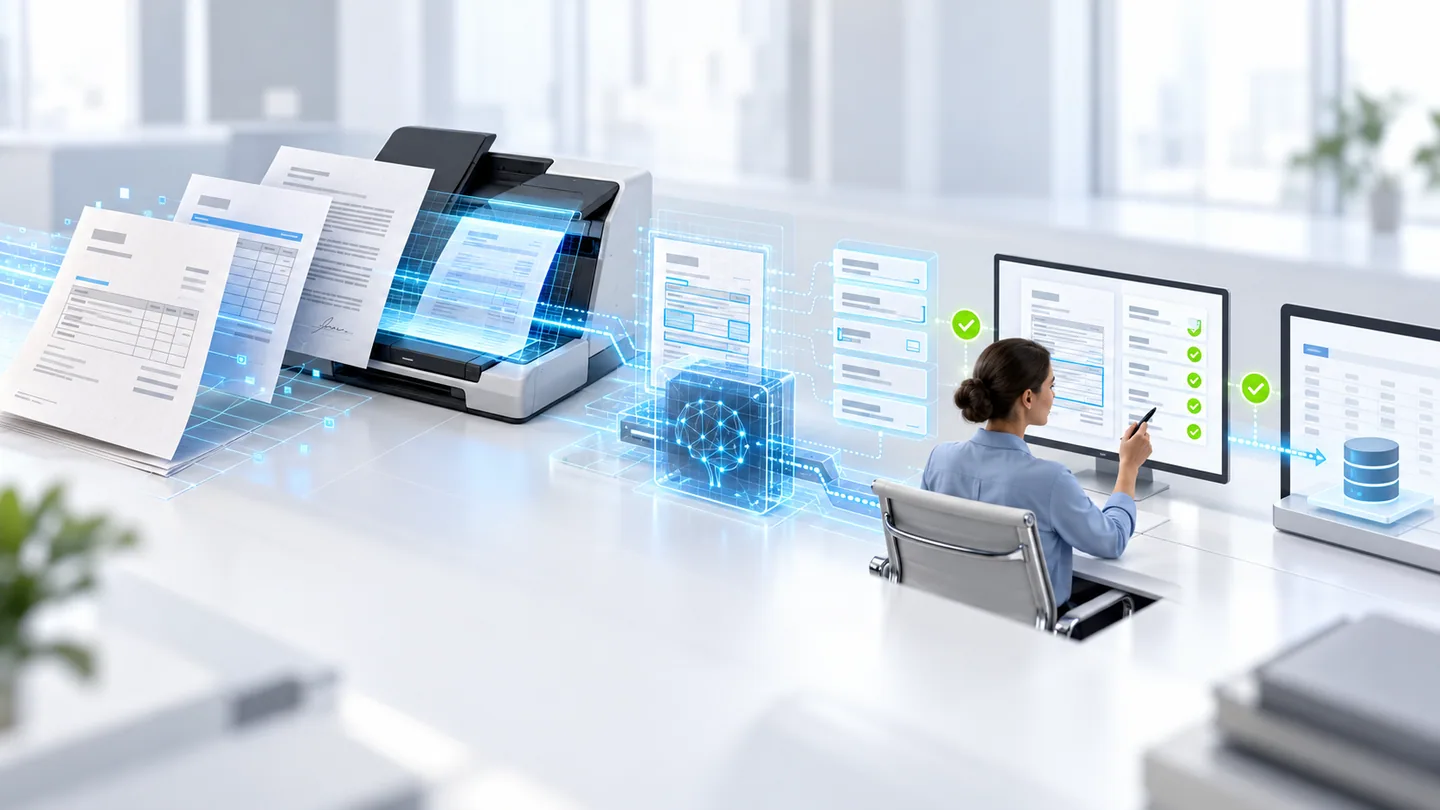
1. Intake and consent: accept documents through an approved channel, verify the case and customer context, scan for malware, and attach source and upload metadata. Preserve the original securely and avoid asking customers to resend data already held lawfully.
2. Page and document classification: detect file type, page boundaries, language, and document class. Split combined uploads into logical documents and flag unreadable or unsupported pages instead of silently assigning a likely label.
3. OCR and extraction: recognize text and layout, then extract required fields into a typed schema. For multi-page tax returns or bank statements, capture period, totals, schedules, account identifiers, and page-level provenance as applicable to the product. Store the source page and region for each extracted value so a reviewer can verify it.
4. Validation and reconciliation: apply format, arithmetic, date, and cross-document checks; compare values with the application and authoritative sources where permitted. Confidence thresholds should be calibrated on representative documents. Low confidence, conflicting records, suspected alteration, or missing pages must go to a trained reviewer.
5. Decision support and audit: send only validated facts and explicit exceptions to downstream KYC or credit workflows. Keep the decision authority and risk rules separate from extraction. Record correction history, evidence references, model and schema versions, reviewer actions, and the final disposition with access and retention controls.
Explore: AI document processing from OCR through workflow automation
Handle sensitive documents with least privilege
Tax returns, bank statements, identity documents, and ownership records contain highly sensitive personal and financial data. Encrypt them in transit and at rest; restrict access by role and case; separate production, testing, and model-evaluation data; and prevent document contents from leaking into general analytics or support logs. Confirm how vendors process uploads, derived text, and temporary files, including retention, support access, subprocessors, and deletion.
Use synthetic or appropriately de-identified examples where feasible for testing, and verify that redaction has not left identifiers in headers, metadata, or OCR output. Define retention periods by record type and legal basis. Ensure that staff and customers can correct extraction errors without overwriting the original evidence or losing the audit trail.
Distinguish document extraction from identity assurance
Reading a name and document number does not establish that a document is authentic, that the applicant owns it, or that the customer satisfies the institution’s due-diligence requirements. Keep extraction, document checks, identity verification, screening, and risk review as explicit steps with their own evidence and decision owners. A high OCR confidence should never be substituted for a completed verification process.
FATF’s digital-identity guidance addresses assessing identity systems for customer due diligence using a risk-based approach. Apply the relevant jurisdictional requirements and institution-approved controls to the actual onboarding product. A document-intelligence component can prepare evidence and identify discrepancies; it cannot independently establish compliance merely because the fields were extracted successfully. FATF guidance on digital identity.
Give reviewers a discrepancy packet instead of a confidence score
For an application with inconsistent addresses, show the conflicting values, document dates, source pages, and validation results together. Preserve both the original and corrected value with the correction reason. A reviewer should not need to search through every page to understand why the case was escalated. Route missing evidence back to the appropriate collection step rather than asking the model to infer it.
Evaluate field-level correctness and case-level outcomes separately. Track unreadable documents, unsupported types, conflicts, reviewer time, and incorrect acceptance after review. Include multi-page statements, duplicate pages, cropped identifiers, and documents from supported languages. Measure where the workflow actually reduces elapsed time, while retaining the institution’s required decision and evidence controls.
Prove the operational benefit before scaling
Pilot one document family and one onboarding segment. Compare the current baseline with the assisted workflow on median and tail processing time, straight-through rate, field-level accuracy, correction time, false acceptance, exception rate, and customer resubmission. Segment results by document quality, language, and relevant customer groups to find uneven performance.
Do not optimize only for automation rate. A system that completes more files but misses key fields or creates extra compliance work is not an improvement. Have operations, compliance, model risk, privacy, and security sign off on the scope, acceptance threshold, escalation rules, monitoring plan, and rollback trigger before expanding to additional documents or products.
Explore: human review and approval patterns for sensitive workflows