Map where sensitive data can leave your systems
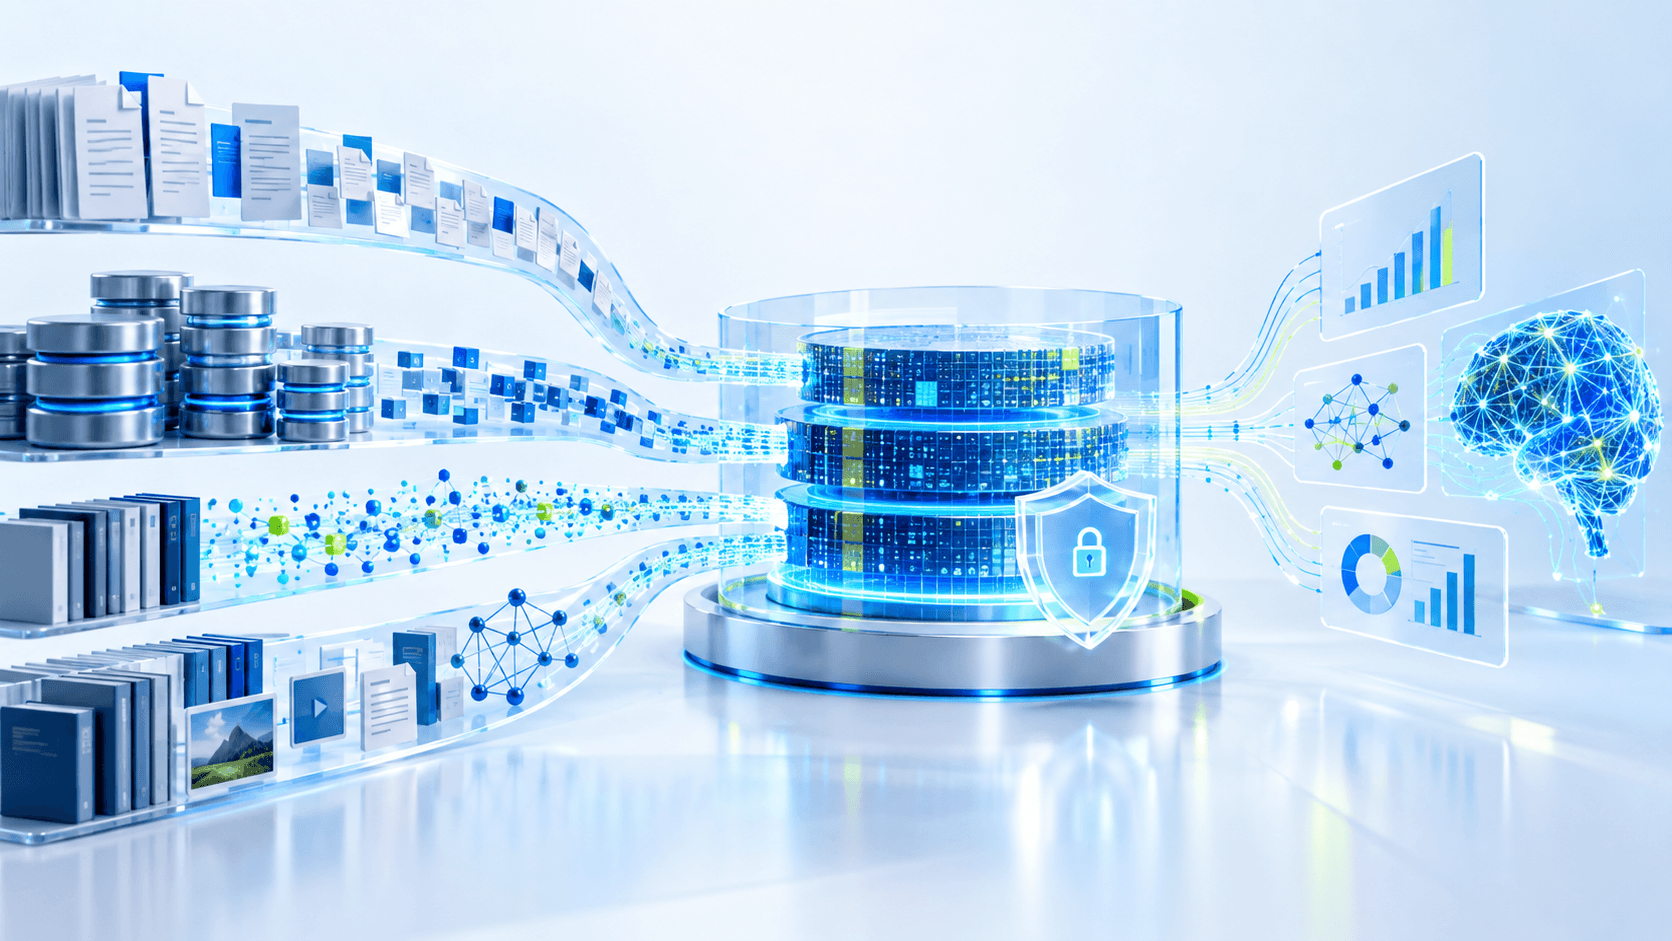
Customer records, payment details, financial forecasts, employee information, and confidential documents can enter an AI system through prompts, uploaded files, retrieval indexes, tool calls, or application logs. Start with a data-flow map: identify each source, model provider, subprocessor, storage location, telemetry path, and human reviewer. Include browser-based public tools as well as approved APIs and internally hosted models.
Classify the data and the purpose before selecting an architecture. Some tasks can use synthetic examples or aggregated information. Others require a controlled retrieval system or a model endpoint under specific contractual terms. Set rules for prohibited inputs and approved use cases, and make them practical enough that employees do not route around controls to get their work done.
Minimize, redact, and pseudonymize before inference
Send only the fields needed for the task. Replace direct identifiers with tokens where possible, remove unrelated account history, and avoid sending full payment credentials or secrets. Pseudonymization reduces direct exposure but can still be personal data when a separate key can reconnect it to a person; secure that key and restrict who can use it. Do not describe reversible masking as anonymization.
Use deterministic validation and a tested redaction layer at the application boundary, not just a prompt that asks the model to ignore sensitive information. Check both input and output for data that should not be disclosed. Be careful with logs, traces, analytics, and debugging: they can recreate the same exposure even when the main model request is protected.
Verify provider, retention, and deployment controls
Review the exact service, endpoint, account configuration, contract, and retention setting in use. Zero-data-retention availability can depend on provider, product, endpoint, eligibility, and feature; confirm it in writing and test the operational configuration. Check training use, abuse monitoring, region, subprocessors, encryption, deletion, incident notification, and how tool or file data is handled. Public consumer terms and enterprise API terms may differ.
A private LLM deployment can improve control over network boundaries and data handling, but it also shifts responsibility for access, patching, monitoring, model updates, capacity, and incident response to the organization. Choose it for a documented requirement, not as a label that guarantees privacy. Test the entire path, including search indexes and backups, and keep a rollback option.
Explore: human oversight and guardrails for customer-facing AI
Apply permissions to derived data and caches
A private document can leak through an answer cache even when the retrieval layer correctly filters search results. Scope caches to the relevant tenant, user or entitlement set, source versions, and policy context. Recheck authorization before serving a cached answer containing protected information. When access is revoked, invalidate or block affected derived answers rather than waiting for a routine index rebuild.
Treat extracted text, embeddings, summaries, exported files, and evaluation examples as part of the same data inventory. An embedding is not an anonymization guarantee. Define how document deletion and permission changes propagate to each store, including backup retention and operational access. If synchronization health is uncertain, block retrieval for affected data until the permission state can be confirmed.
Rehearse an accidental-disclosure investigation
Create a controlled test where an employee loses access to a restricted document while an old answer remains cached. Confirm that search, generation, conversation history, and exports respect the revised access boundary according to the application’s policy. Also test sensitive content appearing in an error message or support trace. These checks cover paths that a model-provider privacy setting alone cannot protect.
Prepare an incident procedure that identifies the affected source, users, derived stores, provider requests, and retention periods. Assign authority to disable a connector or feature and preserve necessary evidence with restricted access. Assess notification and remediation obligations with the relevant legal and security owners. After recovery, convert the failure into a regression scenario and verify that deletion or invalidation completes across the workflow.
Explore: Building AI-ready data foundations and access metadata
Make compliance and access claims precise
SOC 2 describes an independent examination of controls within a defined scope and period; it does not certify that every use of AI is compliant or that customer data can never be exposed. Review the report scope, exceptions, subservice organizations, complementary user controls, and the service configuration you actually use. Map AI workflows to applicable privacy, financial, contractual, and sector obligations with qualified counsel and security owners.
Enforce least privilege for users, agents, service identities, and retrieval. Keep credentials out of prompts, require approvals for sensitive actions, and retain audit evidence with appropriate access and retention limits. Run tabletop exercises for accidental disclosure and vendor incidents. Review the controls whenever prompts, models, data sources, or integrations change; the privacy boundary is the full workflow, not just the model.