What AI document processing does
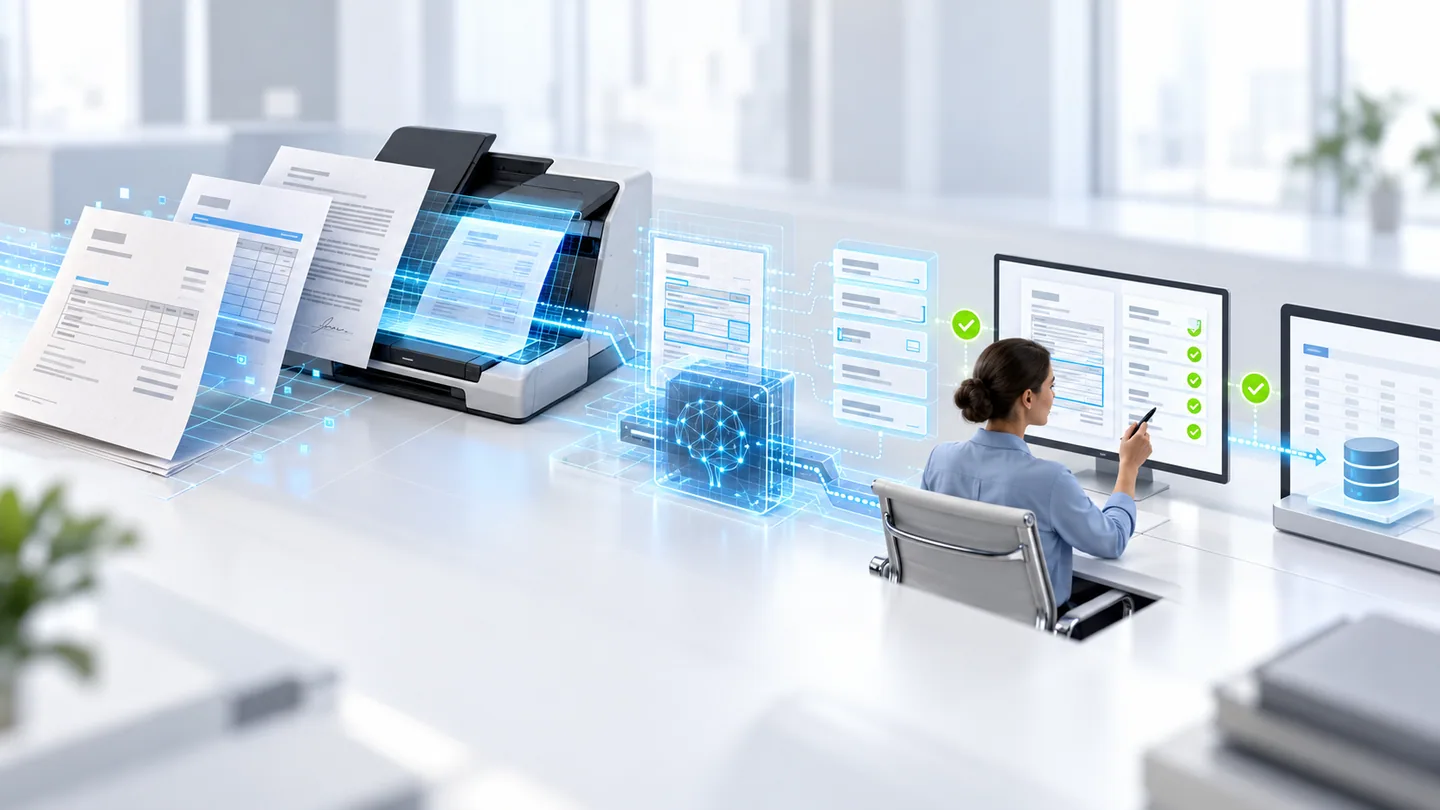
AI document processing converts information in files, scans, images, and forms into structured data or business actions. Optical character recognition (OCR) identifies text; document AI can also classify a file, locate fields, interpret layout, and support validation. An intelligent document processing workflow may receive an invoice, extract supplier and line-item details, compare them with a purchase order, and send exceptions to an accounts-payable reviewer.
The distinction matters because readable text is not the same as correct business data. A process may require understanding which value is the invoice total, whether a date is an issue date or due date, and whether a supplier is authorized. The system should preserve enough context to trace a field back to its page and location, so reviewers can verify it and downstream services can use it responsibly.
Choose a document workflow with measurable friction
Start by identifying document-heavy processes with recurring volume and visible manual work: invoices, purchase orders, claims, onboarding forms, applications, or service records. Map how files arrive, who handles them, which systems receive the data, and where errors or delays occur. Include exceptions such as missing pages, handwritten notes, duplicate submissions, and different supplier templates rather than designing around one clean sample.
Set a baseline for processing time, data correction, backlog, cost, and downstream error before implementation. Clarify which fields matter and how accurate they must be for the next step. A process that can tolerate a person checking an extracted value has a different risk profile from one that automatically approves a payment. The business owner and technical team should agree on these limits together.
Explore: OCR Document Intelligence
Design the intake and classification stages
Normalize files at intake, check format and page integrity, and identify the document type before selecting an extraction path. Classification can direct invoices, contracts, forms, and correspondence to different schemas and review rules. Preserve the original file and assign a traceable record identifier so a reviewer can locate the source when a field is questioned or a workflow needs to be replayed.
Build an explicit route for unknown or unsupported files. Do not force every document into the nearest known class; misclassification can cause incorrect extraction and downstream actions. Validate file security, size, and access permissions at the boundary. If a document contains sensitive information, restrict it to the systems and people that are authorized for that purpose and avoid sending unnecessary content to external services.
Extract fields with confidence and provenance
Define a field schema that reflects how the business actually uses the information: supplier, date, currency, tax, total, reference number, line items, or named entities. Extraction should return values in a consistent format along with confidence and source location where the technology supports it. Keeping provenance makes review faster and helps teams diagnose whether a mistake came from image quality, layout, classification, or an ambiguous source.
Test on representative documents from different sources, layouts, languages, and scan quality. Measure field-level accuracy and document-level completion separately; a workflow can extract most fields correctly while missing the one that determines payment or eligibility. Include blank values, repeated fields, rotated pages, tables, stamps, and handwriting if they occur in real operations. Do not assume performance on one template generalizes to all documents.
Validate extracted data before it moves downstream
Apply deterministic checks wherever possible. Confirm that totals reconcile, dates follow allowed ranges, required fields exist, and identifiers match an authoritative system. Cross-check a supplier against the vendor master or a claim against a policy record, while respecting the access controls of those systems. A model can propose an interpretation; business rules and system-of-record checks decide whether that interpretation is usable.
Set review thresholds according to field risk and confidence. High-confidence, low-impact fields may proceed to the next stage, while uncertain or consequential values enter a review queue. Give reviewers the source image, proposed value, validation result, and reason for the flag in one place. Record corrections in a way that supports quality analysis without using sensitive documents as uncontrolled training material.
Connect document AI to a controlled workflow
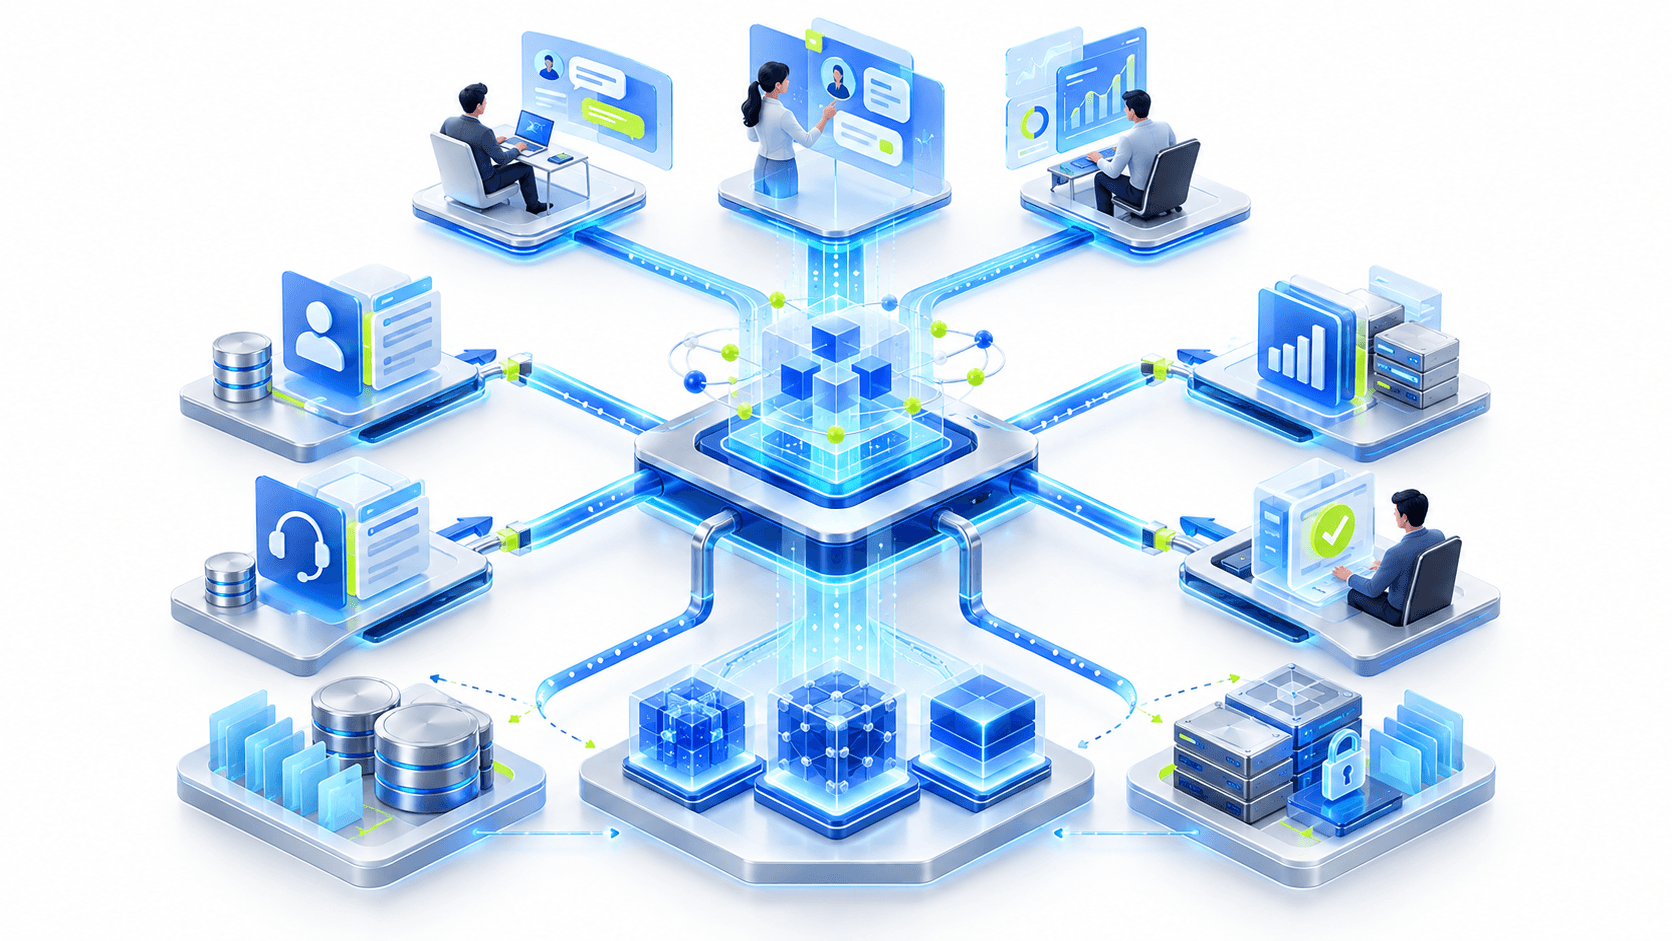
After validation, route structured data to the right destination: an ERP, CRM, case-management platform, data warehouse, or document repository. Use authenticated integrations and narrow permissions. Separate creating a draft record from approving or submitting it. Make updates idempotent so a retry cannot create duplicate claims or invoices, and return clear errors when a destination system is unavailable.
Design for queues, corrections, and recovery as carefully as the extraction itself. A reviewer should be able to accept, correct, reject, or request more information. Preserve status and decision history so work can resume after an interruption. Define who owns unresolved exceptions and how urgent items are handled. This turns OCR output into an accountable business process rather than another spreadsheet that someone must reconcile later.
Measure quality, throughput, and document operations
Track field-level accuracy, straight-through processing, reviewer correction, exception rate, turnaround time, duplicate rate, and downstream rejection. Segment by document type, supplier, form version, or intake channel to identify where the workflow performs differently. Review the cost of rework and human verification alongside model and platform costs. The most useful target is dependable completion at an acceptable cost, not automation percentage by itself.
Monitor changes in source templates, policy, scan quality, and upstream systems. Keep a representative evaluation set and re-test when extraction models, prompts, schemas, or integrations change. FIX Intelligence can help scope OCR Document Intelligence, validation queues, workflow automation, and system integration around the organization’s actual documents. Start with a controlled workflow and expand when both data quality and operational ownership are established.
A sensible rollout often begins with one document class and one destination system. Run the new process alongside the existing method long enough to compare extracted values, review effort, and exception handling. Agree how discrepancies will be resolved and who can approve a corrected record. Before broadening coverage, test new suppliers, form revisions, and poor-quality scans, then update the schema and review rules. This staged approach reduces the chance that a small extraction issue silently propagates into finance, customer service, or operational records.