Start with a decision, not an algorithm
Machine learning development uses data to build and validate models that estimate, classify, rank, detect, or recommend. The useful starting point is not a preferred algorithm; it is a decision or workflow that could improve with a prediction. Define who will use the output, what action it may inform, and what the cost of false positives, false negatives, delay, or uncertainty would be.
Translate the problem into a target variable and a prediction moment. A team forecasting demand needs to define the item, location, time horizon, and when the forecast is available. A classifier needs an agreed label definition and a plan for ambiguous cases. These details determine which data can be used and how performance should be measured.
Establish a simple baseline, such as current rules, historical averages, or the existing manual process. A more complex model is valuable only if it improves the decision after operational cost, review effort, and risk are considered.
Explore: ML Development services
Assess data readiness and prevent leakage
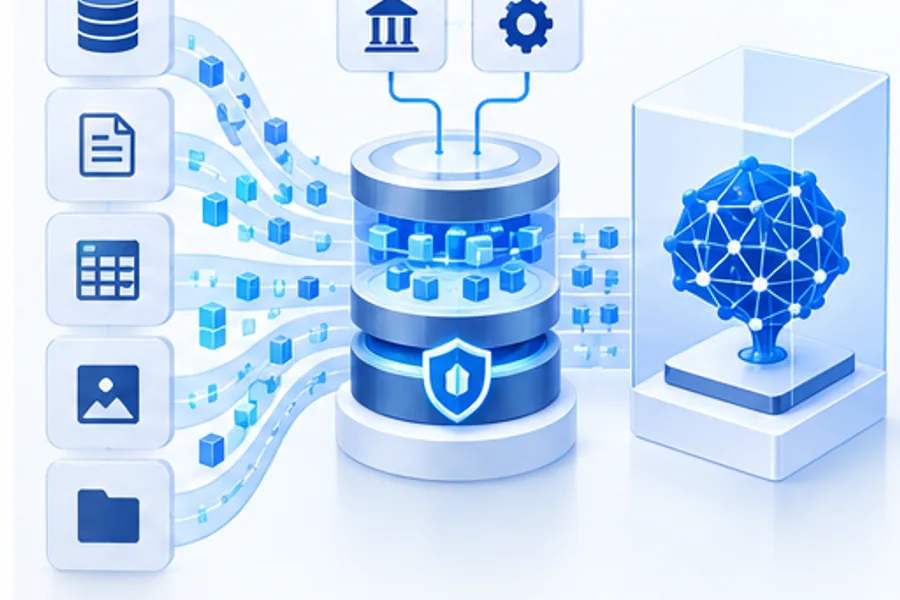
Data preparation starts with provenance, access, quality, and relevance. Identify authoritative sources, ownership, collection conditions, update frequency, missingness, duplicates, and known measurement changes. Confirm that data may be used for the intended purpose and that sensitive attributes are handled under appropriate governance.
Create a dataset that represents the population and conditions where the model will be used. Check label quality, class imbalance, time effects, geographic or product differences, and groups that may be underrepresented. For time-dependent tasks, split training and evaluation data in a way that reflects the future prediction setting. Random splits can produce misleading results when related records or future information appear in both sets.
Data leakage occurs when training or evaluation uses information that would not be available at the real prediction moment, or when records from the same entity improperly cross evaluation boundaries. Document how features are created and when they become available. Have domain and data owners review the design before interpreting model performance.
Build a reproducible model development pipeline
A maintainable ML pipeline separates data ingestion, validation, feature transformation, training, evaluation, and packaging. Version the code, configuration, datasets or snapshots, feature definitions, and model artifacts needed to reproduce a result. Automate routine checks so a change in source data or dependencies does not silently alter the training process.
Compare candidate approaches against the baseline using metrics tied to the decision. Classification may require precision, recall, calibration, and threshold analysis; ranking may need relevance measures and user outcomes; forecasting may need error by horizon, season, or segment. Inspect errors and uncertainty instead of selecting a model solely by a single headline score.
Keep training and inference transformations consistent. Validate input schemas, handle unexpected categories, define behavior for missing features, and test that packaged models run in the target environment. Reproducibility helps teams diagnose whether a change came from data, code, configuration, or model selection.
Evaluate the model in its operating context
Hold-out metrics are necessary but do not prove that a model will improve a business process. Review performance on representative time periods and segments, compare against the baseline, and estimate how decisions change at different thresholds. Include the cost of review and downstream action. When model outputs influence people or access to important resources, add appropriate expert, legal, and governance review.
Check calibration and uncertainty where users rely on confidence. Determine whether the model should abstain or route uncertain cases for review. Explain the limits of feature importance or explanation tools; they can support investigation but should not be presented as a guarantee that a model is fair, causal, or correct for an individual case.
A pilot can test usability, workflow fit, data latency, and adoption with controlled scope. Agree in advance on success measures, stop conditions, and how results will be reviewed. Do not treat a pilot’s selected sample as proof of performance across every site or population.
Deploy with MLOps and clear ownership
Production deployment may be batch, real-time, streaming, edge, or embedded, depending on the workflow’s latency, availability, and infrastructure constraints. Define service expectations, resource limits, access controls, model versioning, and rollback behavior. Use a staged release when possible, and verify that the application handles model errors or unavailable dependencies safely.
Assign both a business owner and a technical owner. The business owner determines whether predictions remain useful and acceptable; the technical owner maintains pipelines, deployment, monitoring, and incident response. Document who approves retraining, threshold changes, new data sources, and changes to downstream decisions.
A model registry and deployment pipeline can improve traceability, but process matters as much as tooling. Teams need repeatable promotion, reviewable artifacts, and an auditable record of what is running and why it was released.
Explore: MLOps services
Monitor drift and manage the model lifecycle
Monitor the health of the serving system and the behavior of the model. Technical measures may include availability, latency, resource use, and input validation errors. Model measures may include input distribution, missing features, prediction distribution, calibration, and outcome quality when labels become available. Business measures should track whether the supported decision or process is improving.
A change in input distribution is a signal to investigate, not automatic proof that a model has become unusable. Determine whether data collection, user behavior, policy, or the underlying process changed. Set thresholds and response owners, then decide whether to recalibrate, retrain, roll back, or pause use. Preserve previous model versions and evaluation evidence to support safe comparison.
FIX Intelligence supports ML development from data readiness and problem framing through model engineering, validation, deployment, and MLOps. A production model is a maintained part of a business system, with a lifecycle and accountable owners—not a file that is handed off after training.