The scope of Generative AI engineering
Generative AI Engineers build and operate software systems that use generative models to create or transform content. They may work on model APIs, inference infrastructure, retrieval-augmented generation, structured extraction, tool use, evaluation pipelines, or product integrations.
The job is not limited to prompt engineering. It includes building data paths, designing interfaces, validating outputs, measuring quality, controlling costs, and helping teams manage model changes. Strong software engineering and systems thinking remain foundational.
Engineer the full application stack
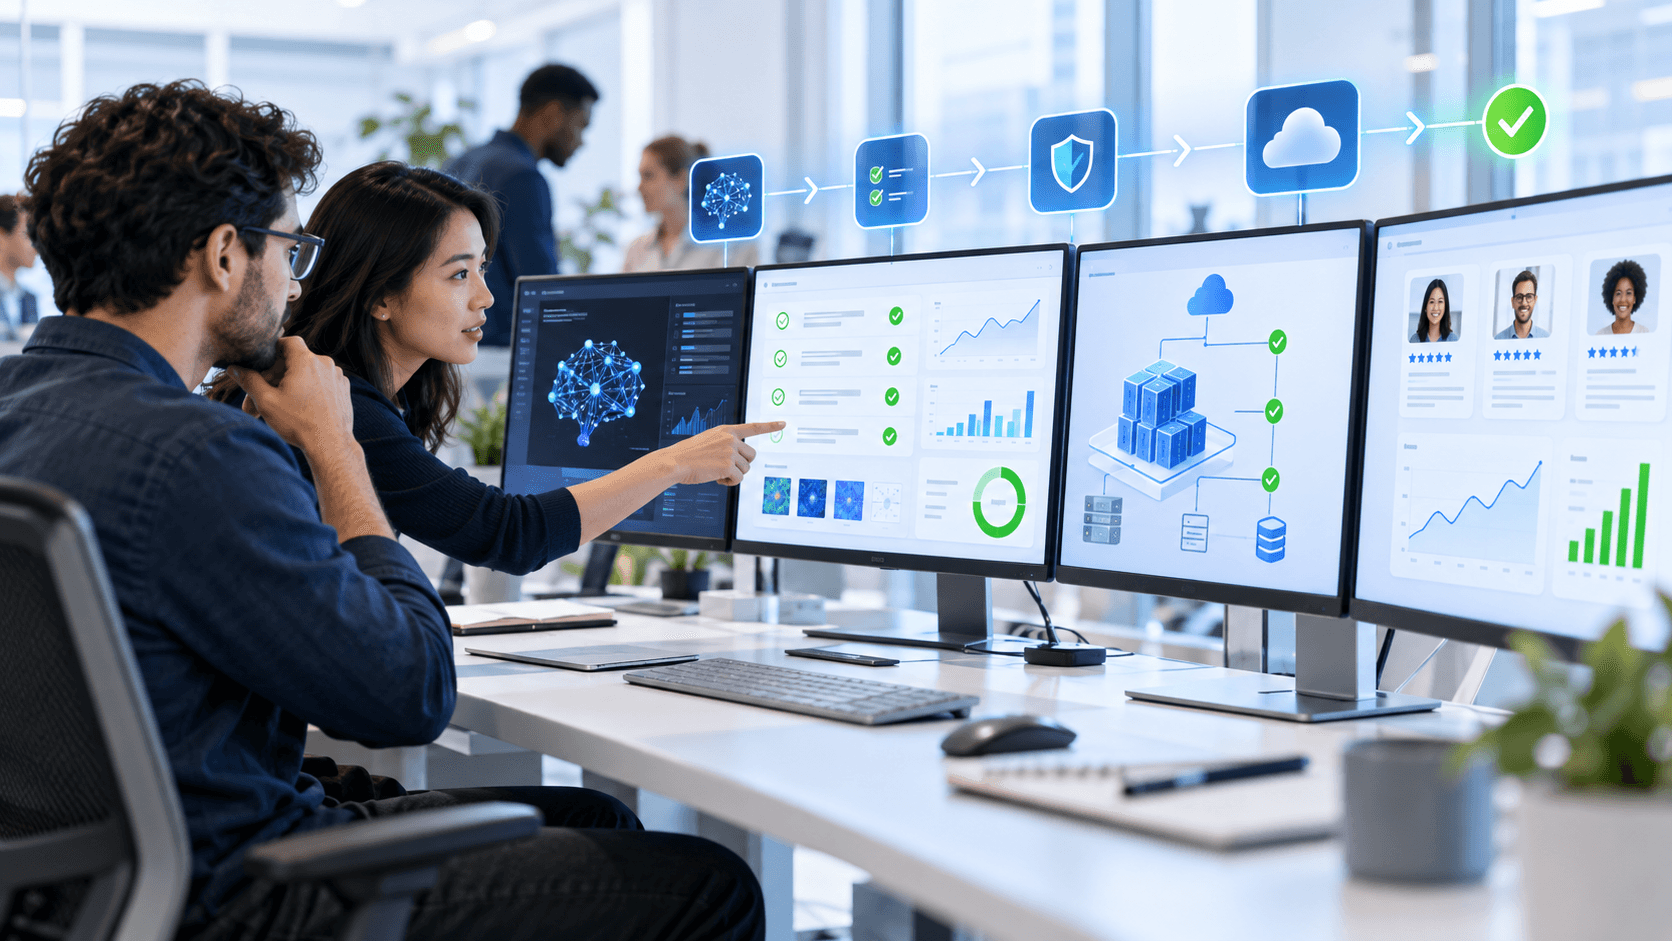
A production system may include document ingestion, parsing, indexing, retrieval, model calls, post-processing, application APIs, user review, and analytics. Make component boundaries explicit and version the configuration that influences output. Preserve traceability while collecting only the data required for operation and evaluation.
Keep deterministic logic in conventional code. Use schemas and validation for structured results, explicit timeouts and retry limits for external calls, and clear handling for empty or malformed output. When a model can invoke tools, implement authorization and validation inside the tool service rather than treating instructions as a security control.
Build evaluation into the development loop
Define what a good result means for the workflow: groundedness, extraction accuracy, task completion, instruction compliance, or another domain-specific measure. Create representative examples and edge cases, and have subject-matter reviewers assess the dimensions automated metrics cannot reliably capture.
Use evaluations to compare prompts, retrieval strategies, and model choices before release. Include missing or conflicting sources, long context, ambiguous questions, prompt injection, and provider errors. Re-run the suite whenever relevant components change. A few anecdotal examples are not enough to establish that a revision improved quality.
Manage security, privacy, and cost
Map where data is collected, stored, retrieved, sent to providers, and logged. Apply identity-aware access to source material, minimize sensitive content, and establish retention and deletion behavior. Review provider terms and deployment options against the data and operational needs of the use case.
Measure cost per accepted task, not only cost per token. Track context size, retrieval volume, retries, model tier, latency, and human correction effort. Use budgets and approved routing strategies without silently degrading quality. Monitor unusual usage and set graceful fallback behavior for quota or provider incidents.
Version the dependencies that determine an answer
For a retrieval application, an answer depends on more than the model name. Record the prompt configuration, parsing rules, embedding configuration, index version, retrieval filters, ranking settings, and tool contracts used in a release. Keep these identifiers with the evaluation evidence and the approved deployment. This allows an engineer to investigate a changed answer even when the application code itself has not changed.
A document update may justify refreshing an index without changing the model. A parser change may require rebuilding derived content. Document those dependencies so release tooling can rebuild the necessary artifacts and invalidate stale caches. Avoid collecting complete documents in traces when identifiers and authorized source links are enough for investigation.
Use component-level evidence to diagnose a failed answer
When a knowledge assistant returns the wrong policy, first check whether the correct source was ingested and accessible to the user. Then inspect retrieval, ranking, context construction, generation, and citation mapping. Assign the failure to the responsible component and create an evaluation case that reproduces it. A model upgrade should not be the default fix for missing or incorrectly filtered evidence.
Define release gates for the failure modes that matter: unauthorized retrieval, unsupported material claims, incorrect citations, and unsuccessful actions presented as complete. Combine automated checks with domain review and record what each check cannot establish. Roll out a revision to a limited audience, compare its quality and operating cost, and keep the previous compatible configuration ready for recovery.
Support dependable production operations
Establish service ownership, dashboards, quality sampling, incident procedures, and a rollback path. Monitor changes in input distribution, retrieval relevance, user overrides, latency, error rates, and downstream outcomes. Model providers and versions can change, so keep configuration and evaluations reproducible.
Roll out gradually and compare against a baseline workflow. Feed incidents and reviewer findings back into data curation, retrieval, product design, and evaluation. Generative AI Engineers create durable value by making a system observable and improvable, not by optimizing a prompt without regard to the surrounding service.