When to extend an AI research team
AI research teams often face a capacity gap between a promising question and dependable evidence. They may need to prepare context, curate datasets, build evaluation harnesses, compare models, or run repeated experiments while core researchers focus on product or scientific work. External research services can add specialist capacity, but should complement internal ownership of the research question and decision.
Start by defining what decision the work must support: select a model, validate a capability, compare a release, investigate a failure, or estimate whether a use case is ready. Then identify the artifacts needed to make that decision, such as a benchmark, dataset, evaluation report, or reusable harness. A scoped question prevents research activity from becoming a collection of metrics that are interesting but disconnected from product and risk priorities.
Use context engineering to make experiments meaningful
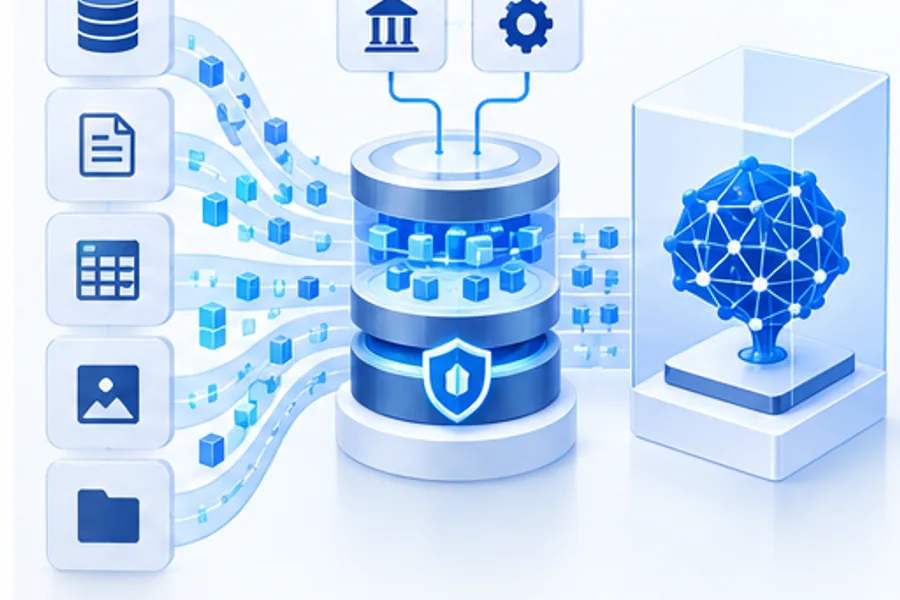
Context engineering prepares the information and tools a model receives so that an experiment reflects a real task. It can include prompt structure, retrieval context, tool definitions, state, examples, and constraints. The goal is not to add the largest possible prompt; it is to provide the smallest relevant, authorized context that allows the model to perform and be evaluated in a reproducible way.
Document the context configuration alongside the model version and test cases. If a benchmark compares two models with different tools, retrieval sources, or instructions, the result may measure the surrounding system rather than the model alone. Design ablations where useful, keep versions, and record what was held constant. Good context engineering makes evaluation more diagnostic and helps teams understand which component drives a result.
Calibrate LLM-as-a-judge with human evidence
An LLM-as-a-judge uses a model to score or compare other model outputs. It can help triage large evaluation sets, apply a rubric consistently, and identify examples for expert review. But an automated judge can inherit preferences, miss domain-specific errors, reward verbosity, or disagree with people. It should not be treated as ground truth simply because its scores are fast or repeatable.
Write a task-specific rubric with observable criteria and examples of boundary cases. Compare judge decisions against independent human labels across the relevant languages, user groups, and output types. Measure agreement and inspect disagreements, especially for high-impact or ambiguous tasks. Calibrate thresholds, blind the judge to model identity when practical, and preserve human review for consequential decisions. Report judge limitations alongside scores so stakeholders understand the strength of the evidence.
Generate synthetic data without mistaking volume for coverage
Synthetic data can create controlled edge cases, balance rare categories, or provide examples when real data is limited or sensitive. It is particularly useful for testing known conditions such as malformed inputs, ambiguous instructions, or language variations. However, generated examples can repeat model assumptions, omit realistic complexity, or accidentally resemble training data. More examples do not automatically mean a more representative benchmark.
Define the gap synthetic data should address and document the generation method, constraints, and review process. Have domain experts examine realism and label correctness; compare distributions with permitted real examples where possible. Keep synthetic and real evaluation results distinguishable. Do not use synthetic data to claim real-world performance without validation. Protect privacy and intellectual property, and check for leakage between generation prompts, training data, and held-out test sets.
Build custom benchmarks that support a decision
A custom benchmark should reflect the workflow, failure costs, and acceptance criteria of the target system. Include representative routine tasks, edge cases, missing context, adversarial inputs, and conditions where the right behavior is to abstain or ask for help. Define expected results, acceptable alternatives, scoring rules, and a held-out set. Keep data provenance, versioning, and access controls so future comparisons are meaningful.
FIX Intelligence, part of FIX Solutions JSC, can support context engineering, evaluation design, synthetic data workflows, and custom benchmarking. An engagement should produce reusable assets: documented rubrics, versioned datasets, test harnesses, human review procedures, and clear limitations. Agree on how internal researchers will operate and extend the work after handoff. The strongest research partnership increases the organization’s ability to answer future questions, not just deliver a one-time report.
Structure an external research engagement for transfer
Before work begins, align on the research question, data access, review cadence, and decision owner. Define how hypotheses will be recorded, which experiments are in scope, and how negative or inconclusive results will be reported. Agree on secure environments, retention, permitted tools, and intellectual-property terms. These details help an external team contribute without creating ambiguity about data stewardship or who may reuse research artifacts.
Make handoff part of the deliverable. Internal researchers should receive runnable code, environment instructions, dataset and rubric versions, known limitations, and a concise decision memo. Schedule a walkthrough and verify that an internal team member can reproduce a sample result. This reduces dependence on a provider and turns short-term capacity into reusable organizational capability. Review the partnership after each phase and adjust scope based on what the evidence reveals.
Measure research value beyond the final score
A research engagement should be judged by whether it improves the quality or speed of a decision, not by the size of a benchmark or the number of experiments. Track time to establish a baseline, the share of findings that are reproducible, the coverage of important risks, and the amount of review effort required. Record inconclusive results and negative findings; they can prevent an expensive product direction from proceeding on weak evidence.
Plan how outputs will fit into the engineering lifecycle. Benchmarks can become release gates, synthetic cases can become regression tests, and context configurations can become versioned assets. Agree who maintains them and how often they are refreshed. FIX Intelligence can help teams build this bridge between research and deployment so evaluation work informs an operating system rather than remaining a one-off analysis.