Why AI agent evaluation needs a workflow view
AI agent evaluation is the structured testing of an agent’s decisions, tool calls, outputs, and overall task completion against defined requirements. A model can produce a fluent response while selecting the wrong record, taking an unauthorized action, or leaving a process incomplete. Enterprise teams therefore need to assess the entire path from user request to verified result, including the systems and people involved.
Traditional software tests remain essential, but they do not fully measure behavior that varies with context, language, retrieved information, and model changes. Evaluation adds repeatable examples, expert judgment, and outcome measures around those variable parts. It should help a team decide whether an agent is ready for a specific role, what boundaries it needs, and which failures require redesign rather than a prompt adjustment.
Define the job and success criteria first
Start with a narrow business job, such as preparing a support response, routing an invoice exception, or assembling an account brief. Write down the user, trigger, expected inputs, authorized tools, completion state, and cases that must go to a person. Ask the process owner what an acceptable result looks like and what errors would have meaningful customer, financial, operational, or compliance consequences.
Turn those decisions into measurable criteria. Depending on the task, the scorecard could include completion rate, factual support, correct classification, tool selection, policy adherence, time to completion, human correction, and cost per accepted outcome. Define how each measure is calculated and what threshold triggers review. A score without a decision rule is interesting, but it does not tell a release team whether to proceed.
Explore: AI security and operations services
Build a representative evaluation set
Collect examples from permissioned, representative work rather than relying on a handful of ideal demonstrations. Include common requests, incomplete inputs, ambiguous instructions, unusual formats, out-of-scope tasks, stale source material, and realistic exceptions. Remove or protect personal and confidential information according to the organization’s data policies. Keep a held-out set that is not repeatedly used to tune the same system.
For each example, document the expected outcome, acceptable alternatives, required sources, forbidden actions, and whether escalation is appropriate. Have domain experts review the cases because a technically plausible answer may still violate a business rule. When possible, add examples from different teams, languages, customer segments, and seasons. A set that mirrors only one operator’s habits can make a system appear more reliable than it will be in wider use.
Use golden trajectories, RL environments, and failure taxonomies
A golden trajectory is a reference path through a task: the starting state, relevant observations, appropriate tool calls, checkpoints, and acceptable completion states. It should not be treated as the only valid path. Agents can solve a task in multiple ways, so score required properties and outcomes while allowing safe alternatives. Include successful references alongside difficult cases, and version trajectories when the environment or tools change.
Reinforcement-learning environments can make agent behavior repeatable across many trials. They should model relevant state, permissions, tool results, timeouts, and failure conditions without exposing production systems. Define environment resets and scoring carefully; an agent can exploit a benchmark shortcut that does not represent real work. A failure taxonomy then groups misses such as planning errors, invalid tool arguments, permission violations, loops, incomplete work, and unsafe recovery so teams can diagnose trends rather than chase individual anecdotes.
For software-engineering agents, use repository tasks with testable acceptance criteria, controlled dependencies, and isolated execution. Measure whether the change satisfies requirements, passes tests, preserves security, and remains reviewable. A benchmark should include realistic bug fixes or scoped feature work, not only code-generation puzzles. Keep held-out tasks and inspect whether results transfer to repositories and workflows that were not used to tune the agent.
Test agent actions, not just generated answers
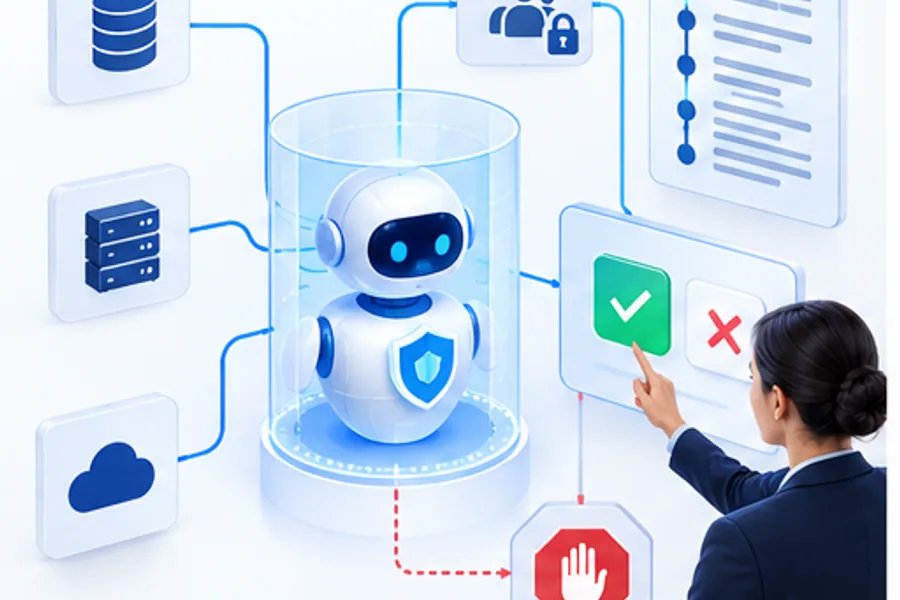
An agent acts through tools, so evaluate whether it selects the right tool, supplies valid arguments, handles returned data correctly, and stops when the next step is outside its authority. Test read and write permissions separately. For consequential actions, verify that the agent pauses for approval and that the approval screen gives a person enough context to make an informed decision. Confirm that rejected or expired approvals do not silently become completed actions.
Include failure and abuse cases: unavailable APIs, timeouts, duplicate events, malformed tool output, prompt injection in retrieved content, conflicting records, and attempts to access another user’s data. Check that retries are bounded and do not repeat a transaction. Measure the quality of fallback behavior and human handoffs. A useful evaluation report records what the system did, what it should have done, and which control or component needs attention.
Combine automated scoring with expert review
Automated checks work well for deterministic requirements such as schema validity, required fields, access boundaries, or exact tool arguments. They can also help compare a response with an expected result when the comparison rules are clear. For open-ended tasks, automated graders may miss nuance or share the same blind spots as the system being evaluated. Treat them as one signal, not a universal quality authority.
Use trained reviewers to assess representative samples, high-impact outputs, and cases where automated scores disagree. Give reviewers a rubric and periodically compare their judgments to improve consistency. Record the type and severity of each failure, not just a pass rate. This combination makes it easier to identify whether the issue comes from unclear requirements, missing data, retrieval, orchestration, model behavior, interface design, or inadequate training.
Explore: AI delivery timeline and approach
Release in stages and monitor real work
Move from offline tests to shadow evaluation, then a small controlled cohort, before broad release. In shadow mode the agent can produce a proposed result without changing the live process; compare its work with what people actually did. During a limited pilot, keep a person able to review or reverse actions, and make the fallback route easy to find. Expand scope only when the evidence meets pre-agreed quality and safety criteria.
After launch, monitor task outcomes, correction rates, escalations, latency, cost, and tool failures using privacy-aware traces. Sample results with process owners and investigate changes in user mix, source freshness, permissions, model versions, and connected systems. Maintain a rollback path and a named owner who can pause the capability. Production evaluation is a continuing operating practice because the workflow around an agent changes over time.
Make evaluation part of the delivery lifecycle
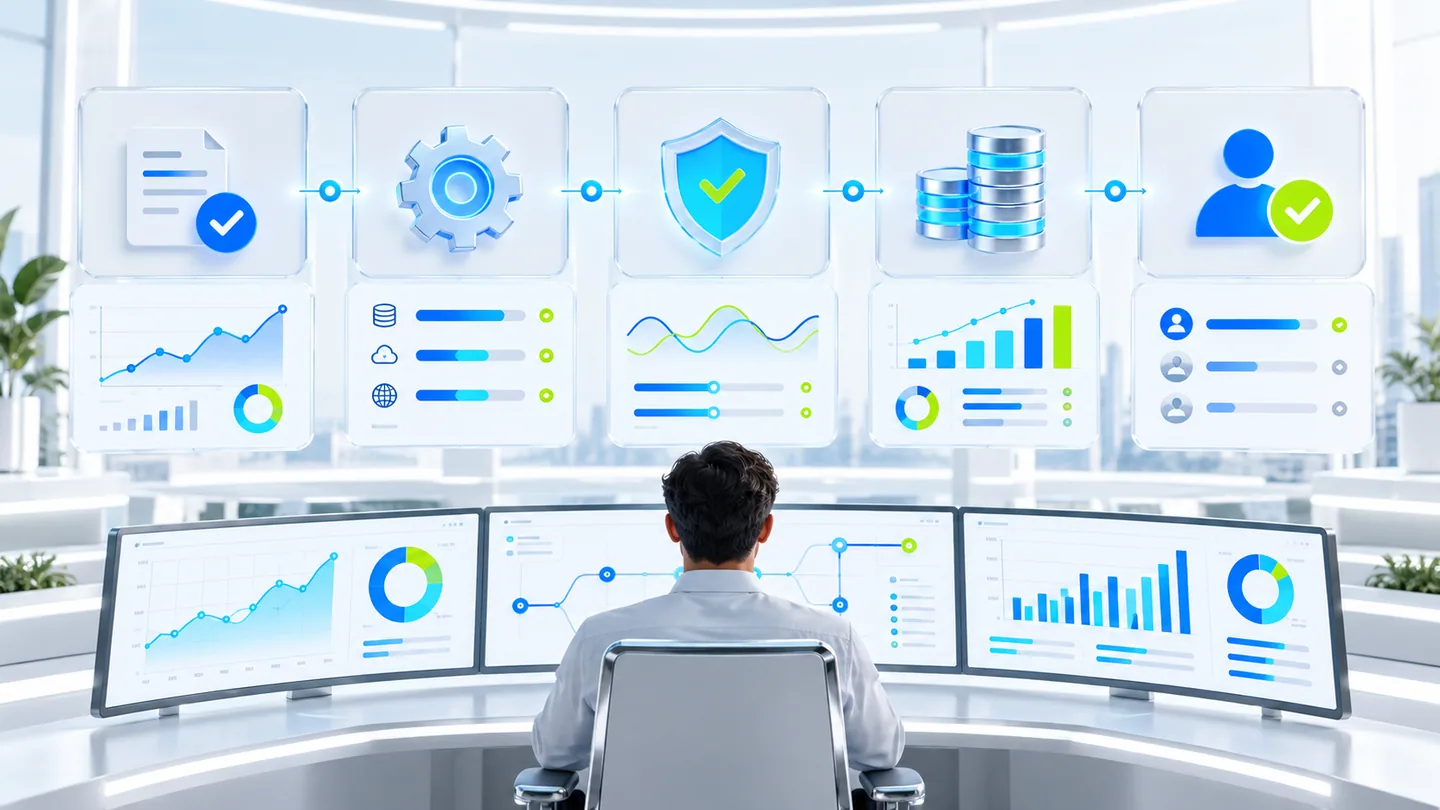
A durable evaluation program connects product, engineering, security, operations, and business owners. Product teams define the user outcome; engineers make tests repeatable; security reviews access and misuse cases; operations prepare incident response; and process owners decide whether results are acceptable. Store evaluation sets and results with system versions so a model or prompt change can be compared with a known baseline.
FIX Intelligence, part of FIX Solutions JSC, helps organizations design AI systems with testable workflows, production controls, and measurable operating goals. A practical engagement can start by selecting one use case, agreeing on its scorecard, and identifying the highest-risk failure modes. That foundation supports a more confident rollout without treating autonomy as a substitute for accountability.
Keep evaluation evidence reproducible. Record the system version, model and prompt configuration, tool definitions, test-set version, scoring rubric, and reviewer notes for each run. When a result changes, this record helps the team distinguish a model regression from a new data source or a changed workflow. Share a concise release summary with the people who own the process: what was tested, what passed, known limitations, and who will monitor the first production cohort. That makes evaluation useful to both engineers and decision-makers.