What frontier AI alignment means to enterprise leaders
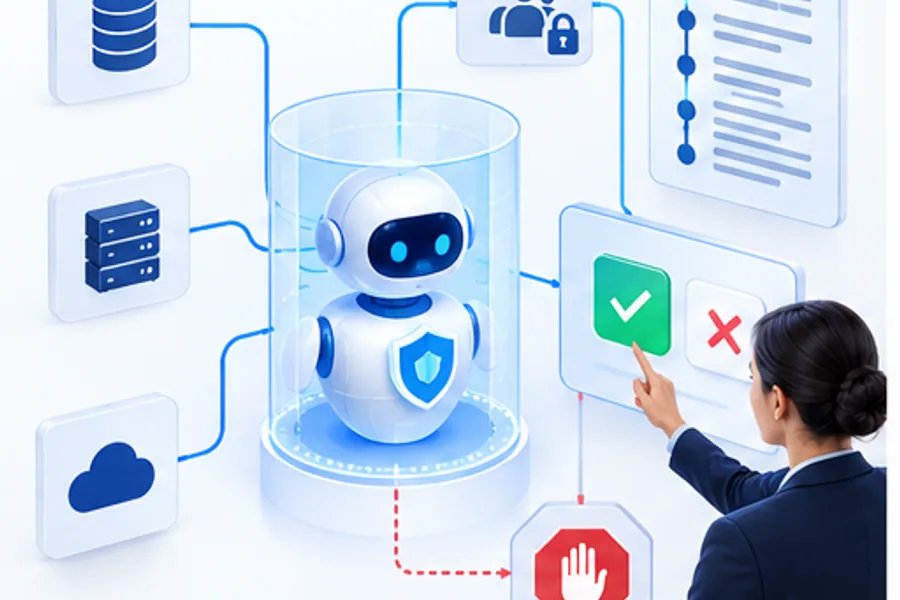
Frontier AI alignment is the work of making a highly capable model behave in ways that remain consistent with its intended purpose, operating limits, and human direction. For a CTO or CIO, the question is not only whether a model can complete a task. It is whether it follows the right instructions, respects data and permission boundaries, communicates uncertainty, and fails safely when the request or context is outside its role.
Alignment is not a single training step or a certificate that guarantees safe behavior. It combines product requirements, representative data, model training, evaluations, adversarial testing, application controls, human oversight, and monitoring after release. A model can appear aligned in a chat benchmark yet behave differently when connected to company knowledge, tools, long workflows, or incentives that reward task completion without accounting for downstream risk.
Use training methods with a clear behavioral objective
Supervised fine-tuning (SFT) teaches a model from curated examples of desired responses or actions. It can establish a consistent format, domain vocabulary, refusal pattern, or workflow behavior. Reinforcement learning from human feedback (RLHF) uses human preferences or judgments to shape outputs toward selected qualities. Both methods depend on the quality and coverage of their objectives: a model may learn what reviewers reward in the examples without learning the wider intent leaders had in mind.
Start by defining the behavior the business needs and the behavior it must avoid. Involve domain experts, security, legal, and operational owners in defining examples and edge cases. Separate must-pass constraints, such as respecting access permissions, from preferences such as tone or brevity. Check whether the training data represents the languages, users, task complexity, and exceptional cases the system will encounter. Maintain provenance and permissions for data used in training or evaluation.
Evaluate behavior, not claims about internal reasoning
Reasoning traces and chain-of-thought (CoT) are sometimes discussed as ways to understand model behavior. Enterprise teams should be precise about what is observable and available: an application may expose tool calls, intermediate task states, citations, concise rationale summaries, or structured evaluation traces, but it should not assume access to a model’s private internal reasoning. Nor should a fluent explanation be treated as proof that a decision is correct or safe.
Build evaluations around observable behavior and outcomes. Test whether the model used authorized sources, selected the correct tool, followed the policy, asked for clarification when required, and escalated uncertain or consequential cases. Keep task traces privacy-aware and document what each trace can and cannot establish. Compare model outputs with independent references and expert review, particularly when a task has meaningful financial, safety, privacy, or reputational consequences.
Red-team the system under realistic conditions
Adversarial red teaming probes how a model and its surrounding application respond to misuse, ambiguity, conflicting instructions, untrusted retrieved content, and operational failure. A useful exercise reflects the actual threat model: which users can access the system, what data it can retrieve, which tools it can invoke, and what actions can affect customers or company operations. Testing a model in isolation may miss vulnerabilities introduced by connectors, prompts, permissions, or the user interface.
Use a failure taxonomy to turn findings into engineering work. Categories might include unauthorized disclosure, unsafe assistance, instruction conflict, unsupported claims, failure to abstain, tool misuse, and ineffective escalation. Record severity, reproducibility, conditions, and mitigation owner. Retest after a model, prompt, data source, or integration changes. Red teaming should be conducted in approved, isolated environments; tests must not target real people, production systems, or third-party assets without explicit authorization.
Create a proportionate alignment lifecycle
Before deployment, identify intended uses, prohibited uses, affected users, data classes, human decision rights, and measurable acceptance criteria. Run offline evaluations, adversarial tests, and limited pilots before granting broader access. For higher-impact use cases, use staged release, approval gates, human review, rollback, incident ownership, and additional independent scrutiny. The control level should reflect potential impact and reversibility rather than the novelty of the model alone.
After launch, monitor quality, user corrections, escalation rates, access events, drift, complaints, and incidents. Review whether the model’s task and context have changed, and repeat relevant evaluations when model versions, policies, data, or integrations change. FIX Intelligence, part of FIX Solutions JSC, helps organizations design AI evaluation, data, and production controls around real workflows. The practical goal is not a claim of perfect alignment; it is a system whose limits are understood, tested, and managed.
What an executive alignment review should ask
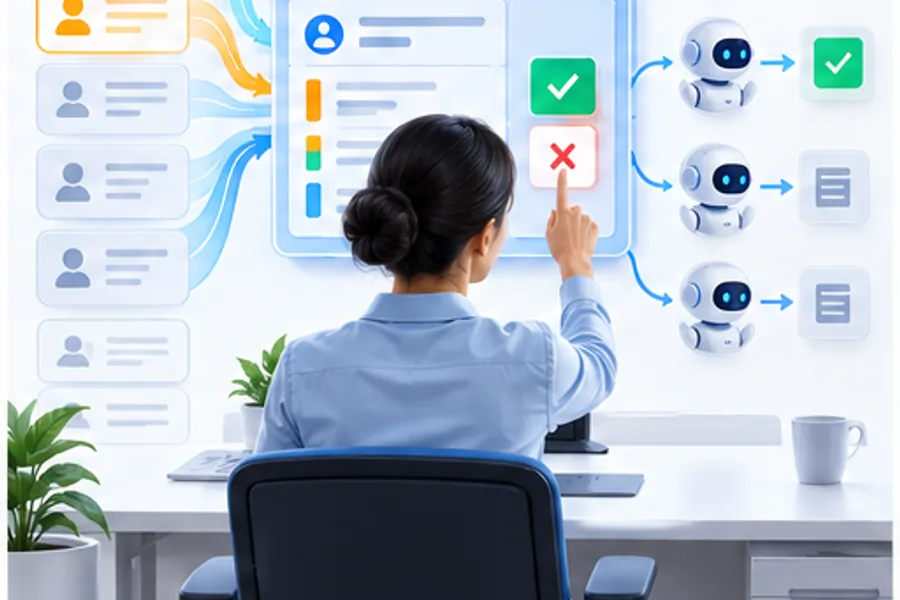
A useful review brings product, engineering, security, legal, and operations together around evidence. Ask which users and processes the system affects, what data and tools it can access, which failures were tested, and what remains unknown. Confirm that a named business owner accepts the intended use and that technical owners can explain the system boundary. If the team cannot state what would trigger a pause or rollback, the launch plan is incomplete.
The review should also examine incentives. If teams are measured only on adoption or task completion, they may discount correction effort, unsafe edge cases, or the ability to abstain. Balance delivery measures with quality, safety, user impact, and incident readiness. Record decisions, assumptions, and follow-up dates. This creates a practical accountability mechanism that can evolve as model capability, usage, and enterprise risk change.
Build an evidence plan before choosing a model
Procurement and architecture decisions should specify what evidence a provider supplies and what the enterprise must generate itself. Request model documentation, change notices, evaluation methods, data-handling terms, and known limitations. Map each claim to a test or operational control. When evidence is unavailable, record the uncertainty and decide whether to narrow the use case, add independent testing, or delay deployment rather than treating missing information as a pass.
A reusable evaluation plan makes later model comparisons more credible. Keep a representative test set, independent reviewers, risk-specific scenarios, and a clear release threshold. Re-run the same core suite after a provider update, then add new tests for newly observed risks. This cadence helps leaders distinguish genuine improvement from a change in benchmark, data, or system configuration.