Define the audit scope before requesting evidence
An enterprise AI audit starts with a specific system and purpose, not a generic inventory of model vendors. Identify the business workflow, affected people, decisions or actions, intended users, deployment locations, data categories, and systems of record. Record whether the organization acts as an AI Act provider, deployer, importer, distributor, or in more than one role; obligations depend on the role and the system’s intended use.
The EU AI Act is risk-based and its obligations apply in phases. Do not infer that every AI use is high-risk, or that a system is out of scope because its model is hosted outside the EU. Check the current consolidated law, applicable guidance, implementation dates, and any amendments with qualified counsel. Switzerland’s revFADP is a separate data-protection law, not an AI Act equivalent; it can apply to personal-data processing connected to an AI workflow even when the AI Act analysis is different.
Use a written scope statement to list the system boundary, owners, jurisdictions, providers, data subjects, intended purpose, and assessment date. Note what is excluded and why. This turns procurement, privacy, security, and legal review into one traceable assessment rather than several incompatible questionnaires.
Step 1: Inventory AI systems, roles, and risk
Maintain an inventory that covers embedded AI features in SaaS products as well as internally built models, APIs, agents, retrieval systems, and employee-facing tools. For each entry, record the business owner, technical owner, provider, model or service identifier, intended purpose, affected users, data types, connected tools, hosting path, and status. Include shadow use discovered through interviews and access reviews; an approved vendor list alone will not reveal every workflow.
Assess the intended purpose and foreseeable use against the AI Act’s categories and applicable obligations. Flag prohibited-practice concerns, potential high-risk uses, transparency duties, and any role-specific requirements for further legal review. Separately assess personal-data processing under revFADP, including purpose, proportionality, transparency, security, data-subject rights, and whether a data-protection impact assessment is required because the processing may involve high risk. Record the reasoning, not just a color-coded score.
Step 2: Preserve model and data lineage
For each material workflow, keep a versioned record of the model or provider endpoint, model version where available, prompt and policy versions, retrieval corpus and index version, tool permissions, application release, configuration, and evaluation results. Record when a component changes, who approved the change, what tests were run, and whether the change affected the system’s purpose, risk, or user-facing behavior. Provider model identifiers can be opaque or change over time, so preserve the contract and provider notices that explain them.
Trace data from source to output: source system, fields and categories used, transformations, access rules, retention, and any external transfer. For retrieval, retain source identifiers, document versions, and access decisions. For training or fine-tuning, capture dataset provenance, collection basis, filtering, representativeness checks, and restrictions. Logs should support investigation without becoming an unnecessary duplicate store of prompts, customer records, or confidential material.
Step 3: Prevent unauthorized exposure of customer PII
Classify inputs and minimize them before inference. Use only the fields needed for the task; remove unrelated identifiers, secrets, payment credentials, and sensitive free text. If tokenization or pseudonymization is used, store the re-identification map separately with tightly restricted access. Reversible masking is not anonymization, and generated or synthetic data is not automatically anonymous.
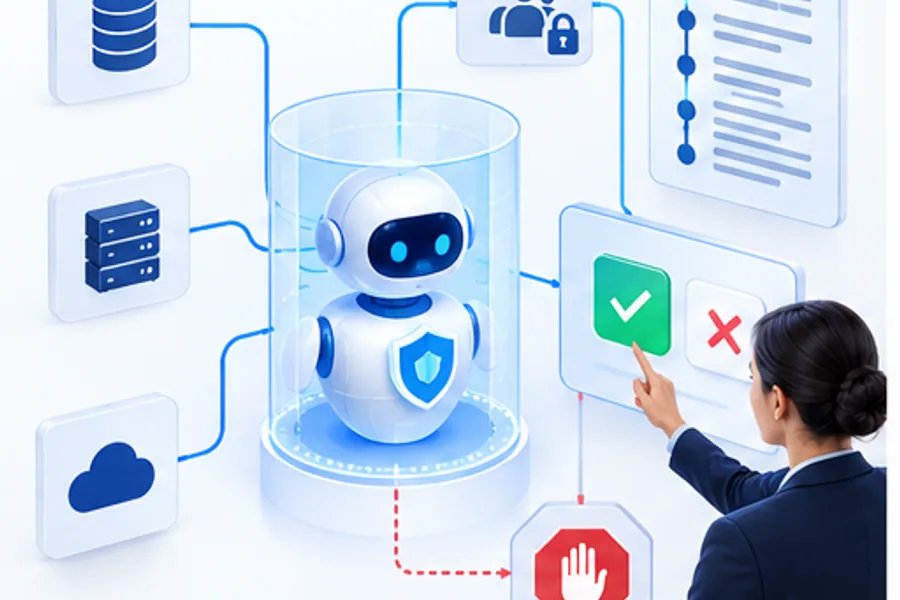
Enforce controls in the application and data layer, not solely through instructions to a model. Apply identity-aware retrieval, purpose-based authorization, input and output checks, secret detection, and limits on copying data into prompts. Prevent retrieval from returning records the caller is not entitled to see. Protect prompts and results in telemetry, traces, support tickets, backups, and evaluation datasets, with documented access and deletion rules.
Document the privacy analysis and the path for handling access, correction, objection, deletion, or other applicable requests. Assign owners for incident escalation and vendor notification. Where a high-risk processing assessment is warranted, involve the privacy lead early and record mitigations and any residual risk before deployment.
Step 4: Prove the data-sovereignty boundary
A “Swiss region” or “EU region” label describes only part of the data path. Map where prompts, retrieved documents, outputs, logs, support diagnostics, backups, and disaster-recovery copies are stored and processed. Identify subprocessors, model endpoints, telemetry services, and the countries from which provider personnel or the organization’s own administrators can access data. Remote access and support access may matter even when the primary database stays in one region.
Define which data must remain within which boundary and whether the requirement concerns storage, processing, administrative access, onward transfer, or all of these. Select on-premises or sovereign-cloud deployment only after testing the complete route, including updates, observability, key management, and incident support. A private LLM deployment can improve control but does not by itself establish legal compliance, security, or sovereignty.
Verify encryption in transit and at rest, key ownership and rotation, tenant isolation, identity federation, network egress controls, retention and deletion behavior, backup location, and the ability to export or erase records. If cross-border transfers are possible, have counsel assess the applicable transfer mechanism and safeguards for the specific data and providers. Capture the evidence and exceptions in the architecture record.
Step 5: Make procurement evidence auditable
Ask vendors for the service and model inventory, data-flow diagram, subprocessor list, hosting and support locations, retention and training terms, incident process, security assurance scope, and change-notification commitments. Request evidence for the exact product, plan, endpoint, and configuration under consideration. A SOC 2 report, ISO certificate, or “zero data retention” statement has a defined scope and does not automatically cover every feature or customer configuration.
Contractually clarify permitted purposes, customer-data use, confidentiality, processing instructions, subprocessors, transfer support, breach notification, deletion and return, audit evidence, model changes, service termination, and assistance with data-subject requests. Include a way to suspend or disable access, export records, and transition to another provider. Security and legal teams should review the actual terms and report exceptions; procurement should not treat a questionnaire answer as a substitute for the contract.
Step 6: Assemble an audit-ready evidence pack
Keep a system card or equivalent record with purpose, scope, owners, architecture, data lineage, provider and model versions, risk decisions, privacy assessment, security controls, evaluations, limitations, and approval history. Link each control to evidence: configuration snapshots, test results, access reviews, change tickets, training records, incident exercises, vendor documents, and human-oversight procedures. Restrict the evidence pack because it may itself contain sensitive operational details.
Before an audit or renewal, sample production traces and confirm that the documented system matches what is deployed. Check that approvals are current, access is least-privilege, logs are retained only as specified, and the tested fallback still works. Reassess after a material change to model, prompt, data source, tool access, purpose, provider, or hosting boundary. A checklist is useful only when an owner can show evidence that each control operates.