What makes a system an AI Agent?
An AI Agent is a system that uses a model to interpret a goal, select from available steps or tools, and continue based on intermediate results. Some agents operate in a fixed workflow with a small amount of model discretion; others choose among tools dynamically. The term covers different designs, so teams should describe the actual capabilities instead of relying on the label.
A conversational assistant may answer a question without changing anything. An agent connected to business tools might retrieve a record, prepare an update, or submit a request. Tool access can turn language output into operational impact, which is why the agent’s identity, permissions, tool contracts, and approval points must be designed explicitly.
Decide when agentic behavior is justified
Use an AI Agent when a process involves variable context or a sequence of bounded decisions that are difficult to enumerate as a simple form or fixed rule flow. Examples include gathering evidence across approved sources, triaging exceptions, or preparing a case for a human reviewer. If a process has stable steps and clear conditions, ordinary application logic may be simpler and more dependable.
Define a measurable success state and a baseline before building. Identify what the agent may decide, what remains deterministic, how uncertainty is handled, and what errors would cost. Compare an agentic design with a simpler workflow; autonomy is only useful when it improves the outcome enough to justify added complexity and oversight.
Bound tools, data, and authority
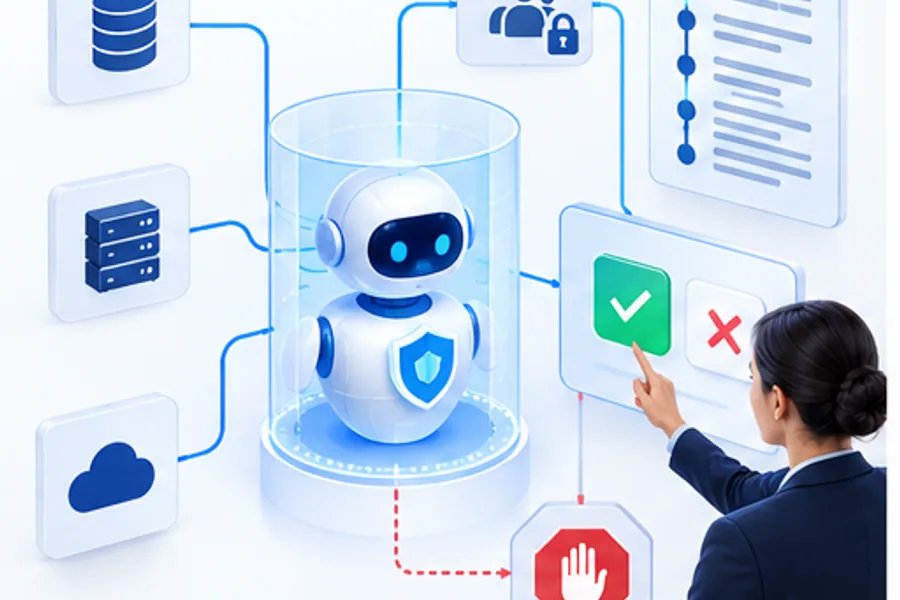
Give each agent only the tools and data needed for its specific task. Prefer narrow, typed operations over broad credentials or unrestricted access. Enforce authorization in the tool and service layer, not solely through instructions to the model. Separate read operations from write operations, and require explicit confirmation or human approval for consequential or hard-to-reverse actions.
Set limits for tool calls, retries, execution time, and total cost. Define a stopping condition and safe behavior when a tool fails, returns conflicting data, or produces an unexpected result. Treat retrieved content and tool outputs as data that may be incomplete or untrusted. Record the decisions and actions needed to investigate incidents without collecting unnecessary sensitive information.
Verify execution and design human handoff
A model response saying “done” does not prove a business action succeeded. Confirm writes through the authoritative system, handle duplicate requests safely, and make partial completion visible. Keep state transitions and calculations in deterministic services wherever feasible. Give the user a clear summary of what was attempted, what succeeded, and what still needs attention.
Escalate when intent or identity is unclear, the request exceeds scope, confidence is insufficient for the task, tools repeatedly fail, or the impact requires human judgment. Provide a reviewer with the relevant evidence, actions already taken, and a concise reason for escalation. Make it possible to pause or stop the workflow and ensure that approval screens explain the action being authorized.
Model an agent’s work as explicit case states
For a supplier-onboarding agent, define states such as collecting evidence, awaiting clarification, ready for review, approved, and submitted. The model may suggest the next permitted step, while application logic enforces allowed transitions. Store the evidence and case state outside the conversation so a restart does not erase approvals or cause a submitted request to run again.
Bind approval to the specific proposed action and validated payload. If the supplier details or payment destination change after review, invalidate the approval and request a new one. Avoid broad tools that can read arbitrary databases or execute unrestricted commands. OWASP’s excessive-agency guidance supports limiting tool functionality, permissions, and autonomy; the business service still needs to enforce those boundaries.
Test partial completion and compensation explicitly
Suppose the agent creates a supplier record but fails to attach a compliance document. The case should show the successful record creation and the unfinished attachment. A retry should continue the incomplete step or reconcile the existing result, rather than create a second supplier. Define which actions can be reversed and which need an authorized person to correct them.
Build test scenarios around a timeout after a successful write, a user cancelling during review, a tool returning malformed data, and repeated instructions to bypass approval. Record the allowed final state for each case. Measure verified completion and unresolved partial cases separately. These tests reveal whether the agent is safe to resume and support after an ordinary operational failure, not just whether it can finish an ideal sequence.
Evaluate the agent as a complete system
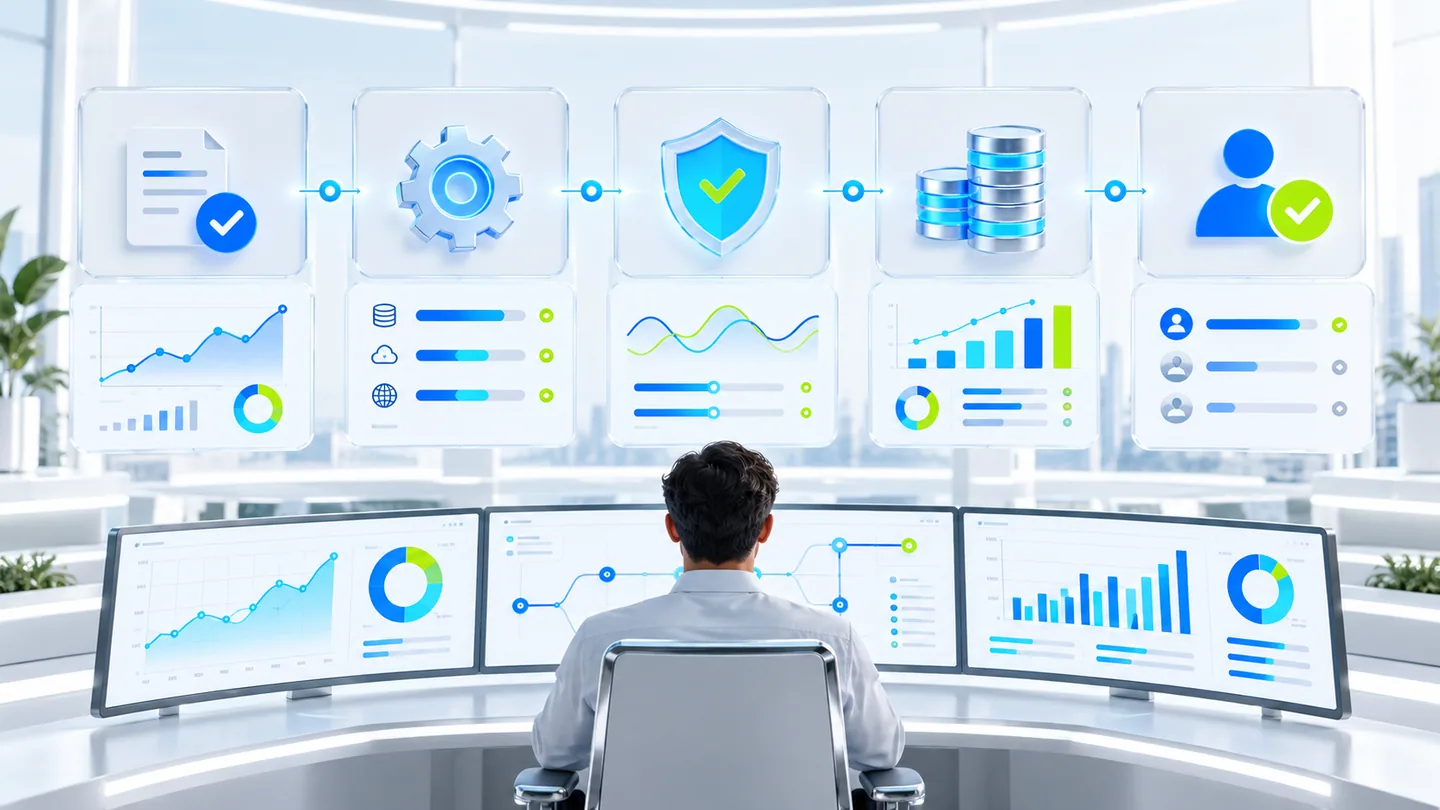
Create representative end-to-end scenarios, including ambiguous requests, missing data, tool errors, conflicting records, policy boundaries, and attempts to exceed permissions. Measure successful task completion, correctness of tool selection and arguments, policy compliance, recovery, escalation quality, latency, and cost. Review traces to understand how failures occur, while protecting personal and confidential data.
Run in a limited environment before granting production write access. Monitor override rates, repeated attempts, incidents, tool failures, quality changes, and cost after release. Version the workflow, tools, prompts, and evaluations together. Expand authority only when the evidence shows that the system performs reliably and owners are ready to operate its failure paths.